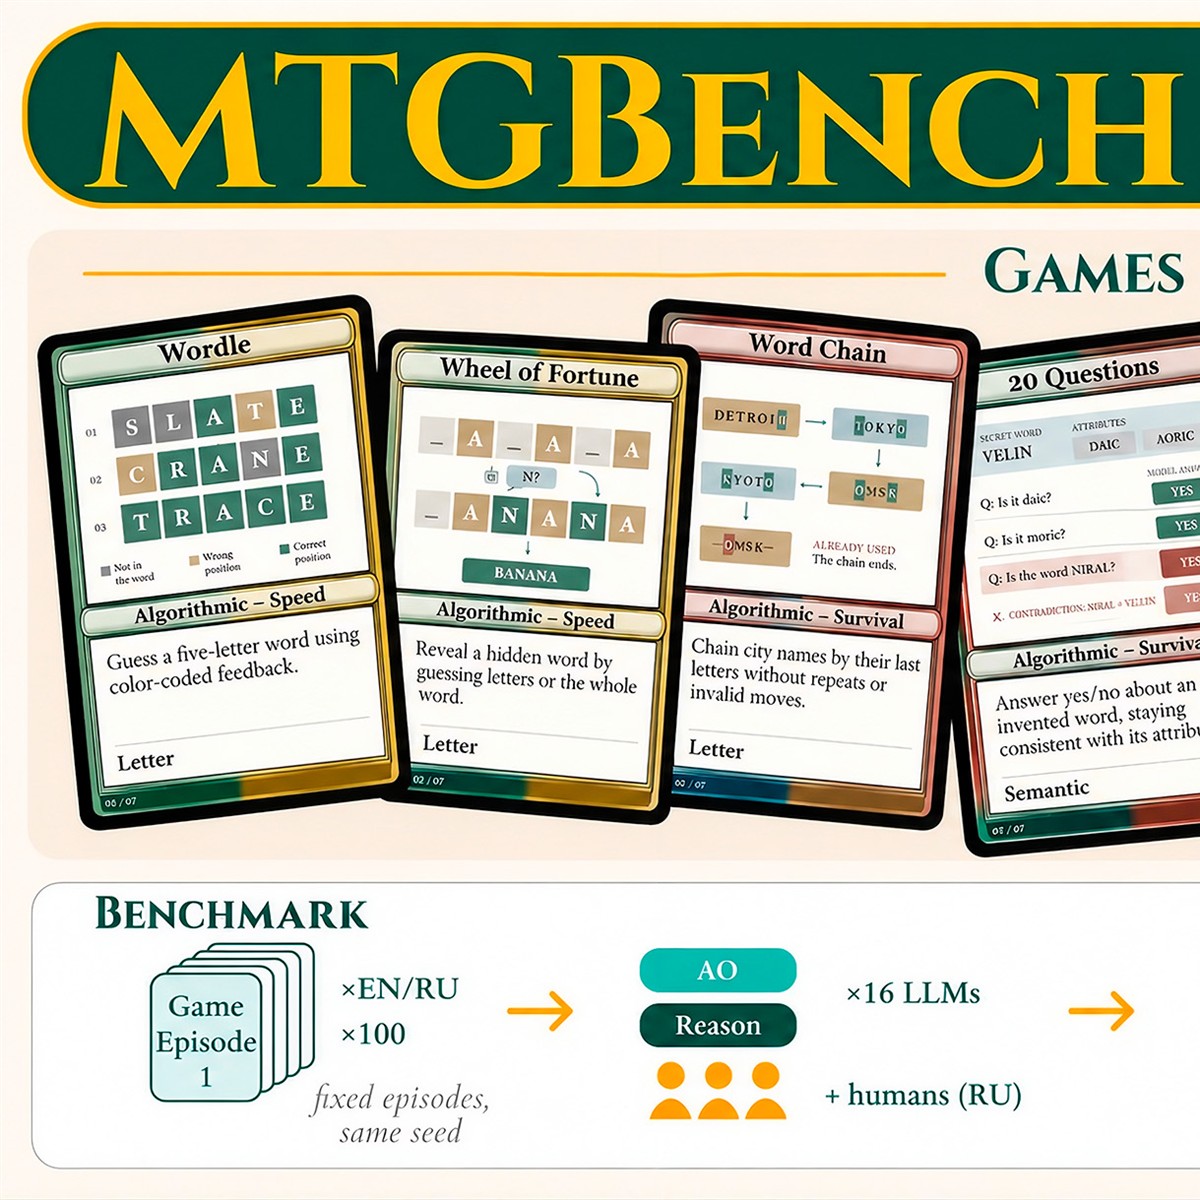
What is MTGBench?
The authors compared 16 models and included human evaluation. According to the announcement, models performed worse on average on Russian tasks than on English ones. This applies to this set and experimental setup, not to every Russian-language task.
What the test measures
For business, it can be a stress test for a chat model or agent when a workflow has steps and constraints. But the result does not directly predict how well a model will process an order or find a clause in a contract.
Applying the approach
Separate evaluation into factual accuracy, rule compliance, tool use, handling of conflicting information, and Russian-language quality. Record model version, system prompt, generation settings, and each scenario result.