The goal: accelerate document entry without losing control
Invoices, delivery notes, and acceptance certificates look like an ideal task for a multimodal model: upload a PDF, ask for JSON, and write the result to an accounting system. That works in a demo. The production risk begins when a probabilistic answer becomes an accounting fact without independent validation.
The errors are concrete. A misread date changes the accounting period, an incorrect tax identifier links the document to the wrong vendor, a missing line changes the total, and a confidently invented contract number creates a false basis for a transaction. Architecture should therefore be organised around a traceable data route, not around a “smart model.”
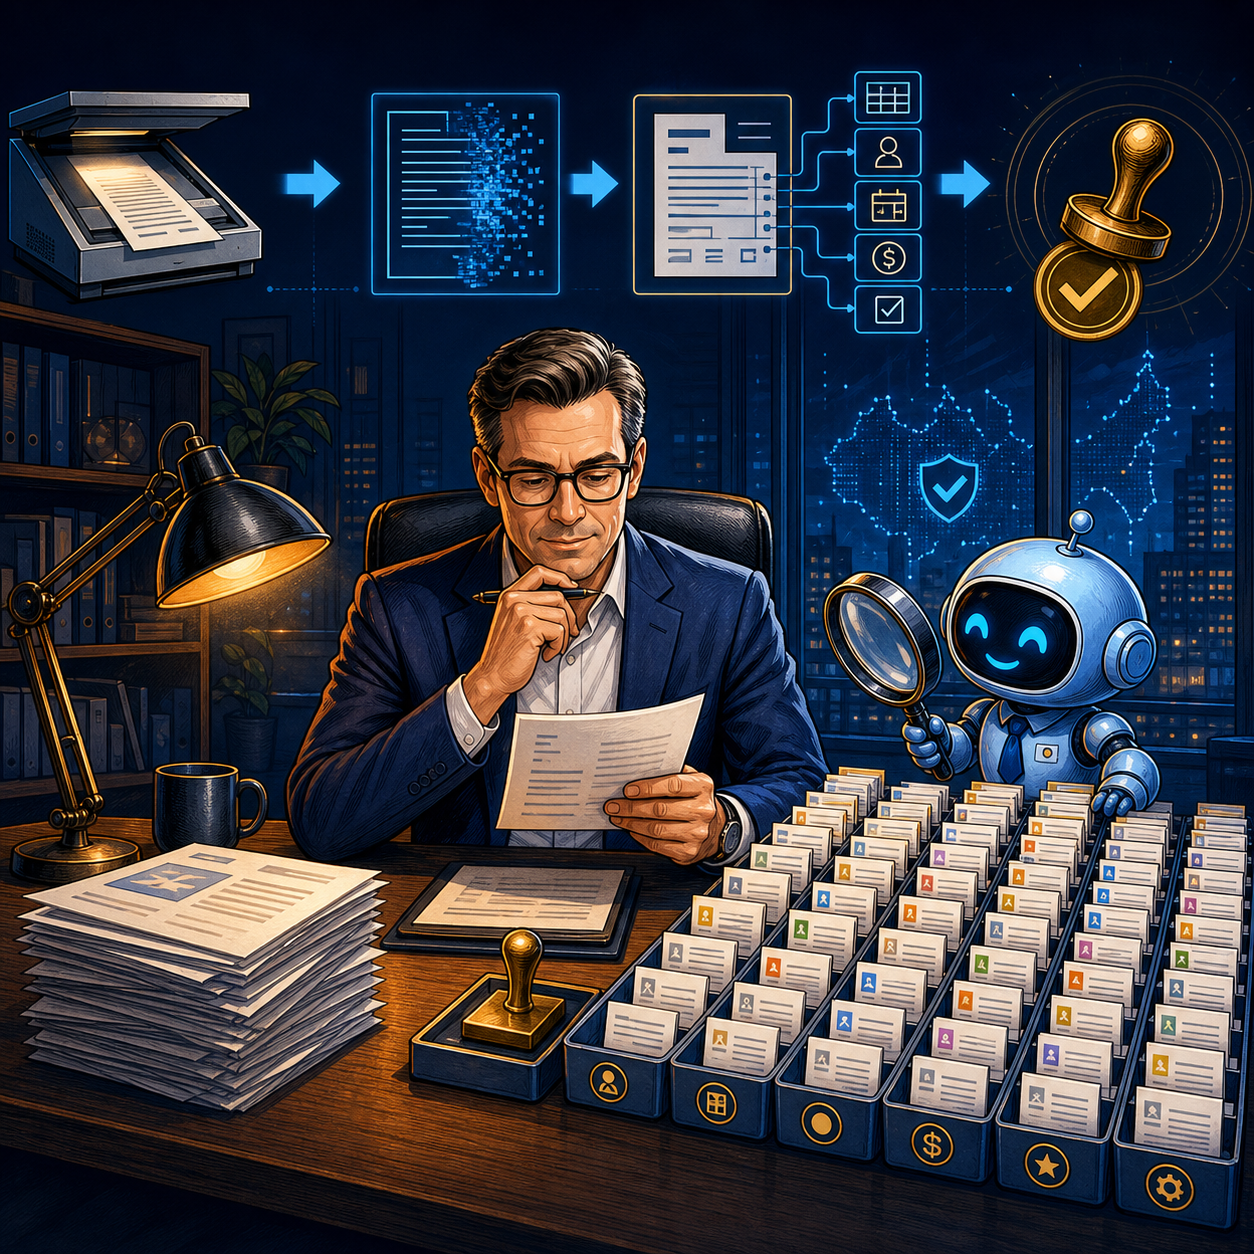
A practical local pipeline separates five functions:
- file intake and quarantine;
- extraction of text, tables, and coordinates;
- field normalisation into a strict schema;
- deterministic checks against arithmetic and master data;
- human approval before writing to an accounting, ERP, or e-document system.
AI accelerates reading and proposes structure. Rules verify what can be verified unambiguously. A person decides wherever the cost of an error exceeds the cost of review.
Why one VLM call is not enough
A vision-language model can interpret layout and document meaning, but it generates its answer probabilistically. NIST identifies confabulation as a generative AI risk: a system can confidently present incorrect content. In a financial document, syntactically valid JSON is therefore not the same as a trustworthy record.
There are also routine sources of error:
- a scan is rotated, wrinkled, or photographed at an angle;
- a stamp covers a key field;
- a table continues on the next page;
- a supplier uses an unusual column order;
- a PDF text layer exists but is corrupted;
- decimal separators, spaces, and currency marks are recognised inconsistently;
- the model “corrects” an unfamiliar product code into a similar word.
The result should be stored with provenance: page number, block coordinates, source crop, parser version, confidence, and applied validation rules. The reviewer then sees not only the value in a “total” field but also where it came from.
Layer 1: intake and quarantine
A document arrives through email, an e-document system, a scanner folder, or a supplier portal. Before recognition, the system should:
1. assign an internal identifier;
2. calculate a file hash to prevent duplicate processing;
3. validate type, size, and readability;
4. run malware scanning;
5. preserve the original in immutable storage;
6. route unknown or damaged files to quarantine.
This layer does not require AI. It creates traceability and prevents one attachment from silently becoming several accounting entries. The intake service should not be authorised to change master data or create a payment.
For a local deployment, object storage, a task queue, and PostgreSQL metadata are sufficient. If documents contain personal data, prices, or commercial terms, access to originals and derived page images should be role-based and audited.
Layer 2: document parsing
First determine whether a PDF contains a usable text layer. If it does, direct extraction is usually faster and cheaper than rendering every page as an image. OCR is required for scans, photographs, and damaged PDFs; a VLM is useful for complex layouts or ambiguous fragments.
Open tools can run this stage locally. PaddleOCR's PP-StructureV3 combines layout detection, OCR, table recognition, and optional modules for orientation, rectification, seals, formulas, and charts. Components can be enabled independently, so an invoice does not need to run the entire stack.
Docling converts PDFs, office files, and images into a unified representation, preserves reading order and table structure, exports to JSON or Markdown, and supports local execution, including air-gapped environments. Docling's code is MIT-licensed, but licenses for individual models must be checked separately.
The output of this layer is not a final accounting object. It is a neutral document model containing:
- pages and their dimensions;
- text blocks with coordinates;
- tables with cells and row-column relationships;
- images and stamps as separate elements;
- source values without semantic “correction”;
- parsing quality diagnostics.
Layer 3: extraction into a strict schema
The next service maps the neutral document into a versioned business schema. An invoice schema may contain document type, number and date, seller, buyer, currency, line items, tax, total, and contract reference.
Each field should be an object rather than a single string:
- `raw_value` — what was literally recognised;
- `normalized_value` — date, number, or identifier in a standard format;
- `page` and `bounding_box` — the source location;
- `method` — rule, OCR, or VLM;
- `confidence` — component-level confidence;
- `warnings` — ambiguity and failed constraints.
A VLM is useful here as a fallback interpreter: associating a label with a nearby value, understanding a non-standard table, or classifying the document. It should receive a strict JSON schema and permission to return `null`, rather than an obligation to populate every field. A missing value is safer than an invented one.
Layer 4: deterministic validation
Before an accountant reviews the document, normal code can reject many obvious errors.
A minimum set of checks includes:
- line-item totals reconcile with the document total within an approved rounding tolerance;
- tax matches the rates and taxable base;
- currency belongs to an approved reference list;
- tax and other identifiers pass format and checksum validation;
- the vendor exists in master data;
- number and date do not duplicate an accepted document;
- the contract belongs to the vendor and was valid on the document date;
- the purchase order or delivery exists and quantity stays within tolerance;
- mandatory fields are present;
- critical values are not sourced only from a low-confidence fragment.
Validation should produce reasons rather than one “trust percentage”: `TOTAL_MISMATCH`, `UNKNOWN_VENDOR`, `DUPLICATE_DOCUMENT`, or `LOW_CONFIDENCE_TAX_ID`. These codes can be tested, explained, and used for routing.
Do not merge a business rule with a model answer. If totals fail arithmetic validation, another VLM request does not make the document correct. The model can suggest an alternative reading of a disputed cell, but the result must pass the same rule again.
Layer 5: human approval and controlled write
The review interface displays the original document and extracted fields side by side. Selecting a field highlights the corresponding area on the page. Incorrect or low-confidence values appear first, while reliable recurring fields do not require a complete reread.
Three routes are useful:
- automatic draft preparation when every rule passes;
- mandatory review of specific fields when warnings exist;
- full manual processing for an unknown template, damaged file, or critical mismatch.
Even a “green” document should initially be written as a draft rather than a posted transaction. Final write permission belongs to a separate service with minimal privileges. It accepts only an approved object, stores the operation identifier, and rejects repeated calls with the same idempotency key.
Operator corrections become labelled data, but they should not retrain a model automatically. They first need privacy treatment, label-quality review, grouping by document type, and version control.
How to measure quality
Average OCR accuracy says little about process readiness. Research on invoice information extraction recommends field-level accuracy, exact match, and consistency-check failures. Business evaluation must add operational metrics.
A pilot should track at least:
- exact match for document number, date, tax identifier, currency, and total;
- line-item accuracy and the share of missing lines;
- the share of documents passing rules without warnings;
- the share of fields corrected by an operator;
- median review time per document;
- false and missed duplicates;
- write attempts blocked by idempotency;
- processing cost by document type and page count.
Critical fields need separate thresholds. An error in a comment and an error in the total are not equal. The evaluation set should reflect real suppliers: clean PDFs, scans, photographs, multi-page tables, stamps, handwritten notes, and rare templates.
Local infrastructure
For a pilot processing several thousand pages per month, one application server plus a separate GPU node for heavier models may be enough. Basic OCR and rules often run on CPU; throughput depends on resolution, enabled modules, and input quality. PaddleOCR's documentation explicitly recommends disabling unnecessary components or selecting lighter models when memory or speed becomes a problem.
A practical layout is:
1. Intake API and object storage for originals.
2. A queue separating fast PDFs from heavy scans.
3. Docling or PaddleOCR workers with no accounting-system access.
4. A normalisation and rules service in a separate container.
5. PostgreSQL for metadata, versions, and audit records.
6. An operator review interface.
7. An isolated connector to the accounting or ERP system authorised to create drafts only.
Model and container versions should be pinned, and every upgrade should run against a golden set before production. Local execution prevents external data transfer, but it does not automatically solve access control, backups, or software supply-chain vulnerabilities.
A model cost calculation
Assume a company processes 4,000 documents per month. Manual entry and review take six minutes on average, or 400 hours. The system does not remove review, but reduces it to two minutes for 75% of documents; the other 25% still take six minutes.
The resulting workload is 200 hours: 3,000 documents × 2 minutes plus 1,000 × 6 minutes. That releases 200 hours per month. At a fully loaded labour cost of RUB 900 per hour, the modeled resource effect is RUB 180,000.
Assume infrastructure and support cost RUB 70,000 per month and the pilot plus integration costs RUB 1.2 million. The modeled net effect is RUB 110,000 per month and simple payback is about 10.9 months.
This is not a performance promise. Replace the assumptions with actual document volume, labour cost, exception rate, and error cost. If headcount does not change, released time produces financial value only when it reduces overtime, accelerates period close, or allows the team to handle more volume without hiring.
A four-week pilot
Week 1: choose one document type and 200–500 privacy-treated examples from different suppliers. Approve the schema and critical fields.
Week 2: deploy a local parser, preserve coordinates, and collect baseline metrics. Do not write anything to the accounting system.
Week 3: add arithmetic, master-data checks, duplicate detection, and a review interface. Record the reason for every warning.
Week 4: run the system in shadow mode next to the current process. Compare review time, corrections, and critical errors. Only after acceptance should a restricted connector create drafts.
Define the scale-up gate in advance. For example: at least 99.5% exact match for totals and tax identifiers on the golden set, zero unapproved writes, a minimum 40% reduction in median review time, and viable economics at the observed exception rate.
What managers should take away
Local document processing is a strong AI candidate when the model is not the sole source of truth. A production architecture preserves the original and coordinates, separates recognition from rules, allows `null`, explains each exception, and gives write authority to a separate service only after human approval.
The first management step is not selecting the largest VLM. Take one document type, identify five critical fields, and build a golden set containing real exceptions. If the system cannot show the source of every value and stop safely when uncertain, it is too early to connect it to accounting.