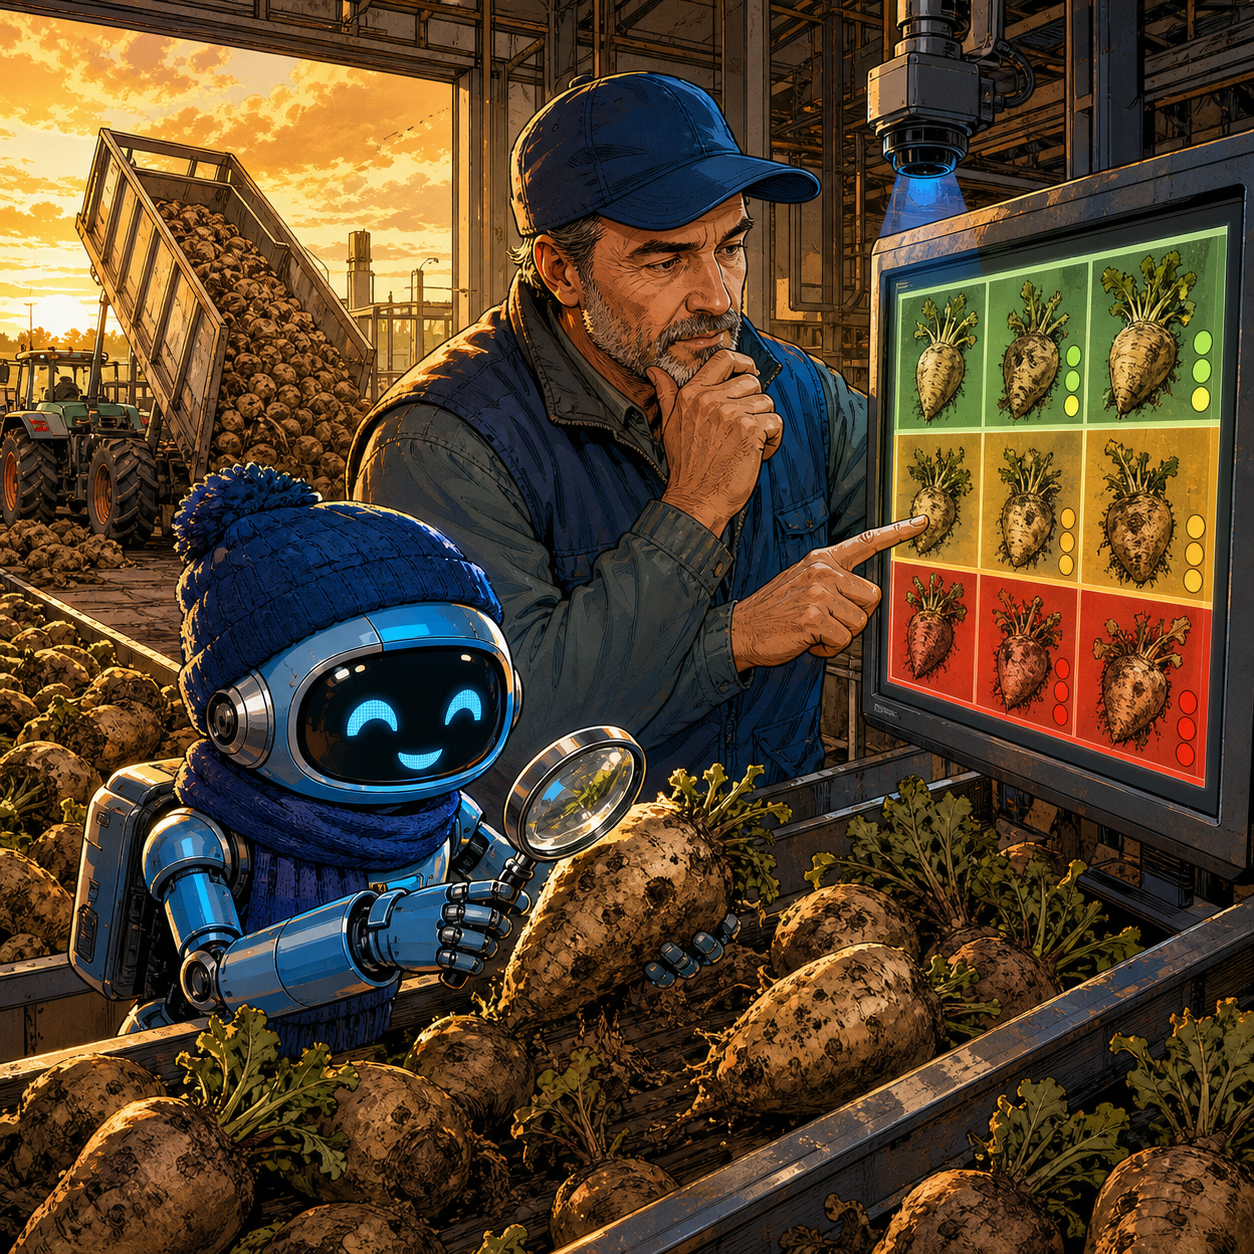
The task was not “deploy AI” but grade raw material consistently
Southern Minnesota Beet Sugar Cooperative is a grower-owned sugar beet cooperative in Minnesota. According to the company, more than 500 shareholder growers produce roughly three million tons of beets annually. During harvest, tens of thousands of truckloads reach intake, and each load must be graded quickly before entering production.
The problem was tangible. Soil and leafy greens arrive with the roots, affecting storage, processing, sugar quality, and settlements with growers. Staff previously performed visual inspections and recorded a binary greens-present or greens-not-present result. At seasonal peak, consistent inspection of every load is difficult: light and weather change, the queue cannot stop, and the boundary between acceptable and unacceptable material remains subjective.
The cooperative and Tactical Edge AI built a computer-vision system on AWS. A camera captures material at intake, a model scores impurities on a continuous scale from 0 to 100, and an established threshold triggers an alert to operations leaders. The machine measures, while people retain the decision and accountability.
AWS reports impurity-detection accuracy above 90%, grading in less than three seconds per load, and up to $5 million in potential annual savings. These are vendor-case metrics and the cooperative's projection, not an independent audit. Their management value is not a promise that another site will reproduce the result. They illustrate a well-chosen process: a high flow of similar objects, a visible defect, a clear financial consequence, and the ability to review disputed cases.
The production architecture
In the published design, the camera and intake lane form the data source. Images are stored in Amazon S3, new-object events start processing through AWS Lambda, and a model is served on an Amazon SageMaker AI endpoint. The result reaches a dashboard and alerting workflow in near real time.
Translated from cloud products into an operating process, the system has five layers:
- **Observation.** A camera must see a consistent working area, not an arbitrary portion of a trailer. Angle, shutter speed, lens protection, supplemental lighting, and synchronization with unloading all matter.
- **Data.** Each image is linked to a load, time, lane, supplier, and capture conditions. Without an identifier, the model produces a number that cannot support supplier disputes or analysis.
- **Model.** Computer vision estimates impurity and returns a numerical score. This is more useful than a binary output because thresholds can change without retraining the model.
- **Rules.** A deterministic layer compares the score with approved boundaries. A normal load proceeds, a borderline load receives another image or review, and a clear exceedance generates an alert.
- **Human and audit trail.** An operator sees the original image, score, and reason for the alert, then confirms or corrects the decision. Actions are stored for disputes and the next training cycle.
In this case, AI is not described as writing directly to grower payments. That boundary matters. The model helps make inspection continuous and consistent, but a quality dispute must follow company policy, preserve evidence, and allow human reconsideration.
Why a continuous score beats yes or no
Binary classification hides operationally useful information. A load with a few leaves and one with significant green material can receive the same label even though their effects differ. A numerical score enables three operating modes:
- green zone: register automatically without slowing throughput;
- amber zone: capture another view or request selective manual inspection;
- red zone: stop the decision and route it to an accountable employee.
Thresholds should not maximize model accuracy alone. The cost of accepting a bad load differs from the cost of delaying a good one. The first sends impurities downstream. The second creates a queue, consumes inspector time, and may create a supplier dispute.
The working metric is therefore the cost of errors per thousand loads, not accuracy by itself. A pilot should count false accepts, false alerts, manual-review share, lane delay, and decisions that operators reverse after seeing the image.
Data required before buying a platform
The central project asset is not a managed endpoint but a representative image archive. Seasonal production is especially vulnerable to collecting an attractive dataset during one sunny week and declaring the problem solved.
The set should contain:
- morning, midday, and evening light;
- dry and wet roots, different soil colours, shadows, and glare;
- different trailers, unloading speeds, and pile heights;
- normal, borderline, and clearly unacceptable loads;
- a human-confirmed grade and the final operating decision;
- technical failures such as a dirty lens, shifted camera, empty frame, and obstructed view.
Training and test sets should be separated by date, shift, or supplier rather than by randomly splitting adjacent frames. Otherwise nearly identical images from one unloading event enter both sets and inflate measured quality.
Annotation also needs a process. If two experienced inspectors frequently disagree, a model cannot learn a more consistent standard than people have defined. First align the instruction, examples of borderline cases, and arbitration mechanism. Sometimes the first project benefit appears before model training: the business formalizes quality criteria that previously existed only in individual experience.
Site and IT requirements
The cloud design in the case suits seasonal demand: storage and compute grow with the intake stream, while maximum infrastructure need not remain active off-season. A Russian operator should separately assess image-transfer rules, network availability, and production-data location.
Three patterns are practical:
- **Cloud.** Cameras send images to object storage and a managed inference service. Scaling is easier, but the lane depends on connectivity and data-processing rules.
- **Local environment.** A model runs on an industrial PC or nearby server, while scores and selected images flow to central systems. Latency and internet dependency fall, but on-site equipment needs support.
- **Hybrid.** Fast grading runs locally, while archival and retraining are centralized. For a critical lane, this is often the most resilient pattern.
Every pattern needs a degraded mode. If connectivity fails, a camera breaks, or confidence is low, the workflow must visibly return to manual inspection instead of silently repeating an old value. Operators should see camera health, time of the latest frame, and model version.
Integration is broader than ERP. The system needs a weighbridge or load identifier, intake journal, quality dashboard, accountable-person alerts, an evidence-image archive, and model-version management. Any financial write should still pass through existing business rules and human approval.
Risks after a successful pilot
Computer-vision quality moves with the physical environment. A new light, replacement camera, repaired conveyor, unusually wet season, or altered agronomy can shift image distributions. The model may still return a confident number.
Production monitoring should track:
- alerts and manual reversals by shift;
- disagreement between model scores and final inspector decisions;
- changes in brightness, sharpness, and working-area position;
- new types of impurity;
- frame-to-decision latency and missing events;
- results from random laboratory or production checks.
Training only on model mistakes is unsafe because the dataset gradually becomes a collection of exceptions. Keep a random sample of normal flow and a frozen test set that does not enter retraining.
There is a governance risk as well. If scores influence payments, suppliers should understand the criteria, appeal process, and retained evidence. A visible score plus the original frame reduces conflict better than the phrase “AI decided.”
Economics without promising $5 million
The $5 million potential belongs to the scale and conditions of one cooperative. Another business should build the calculation from operational units.
Annual value has four components:
- avoided payments or losses from out-of-specification material;
- fewer repeat inspections and less manual reporting;
- reduced downtime and intake queues;
- faster supplier feedback that improves later loads.
Subtract cameras and installation, compute, image storage, integration, annotation, support, retraining, and employee time spent reviewing exceptions. Cost per confirmed grade and cost of an error are more useful than cost per inference.
Consider a modelled example. A site accepts 40,000 loads per season and routes 8% to manual review, creating 3,200 inspections. Reducing false alerts from 8% to 4% releases 1,600 inspections. But if missed bad loads rise at the same time, the labour saving is fictional. Thresholds must minimize total loss rather than produce a convenient presentation metric.
A four-week pilot
**Week 1.** Define one visible defect and one decision it affects. Install a camera without changing the current workflow. Collect frames with grades from two inspectors and measure human agreement.
**Week 2.** Train a baseline model and test it on a different shift or day. Compare false accepts, false alerts, and resilience to light and lens contamination, not accuracy alone.
**Week 3.** Run in shadow mode. The model generates scores and alerts but does not affect production decisions. Operators record whether they agree and how long review takes.
**Week 4.** Calculate the economics of three thresholds, the failure mode, and inspector workload. Enable automatic passage only for a low-risk zone; keep every borderline decision with a person.
The launch criterion is not “the model reached 90%.” Four conditions must hold together: error cost is below baseline, the lane did not slow, exceptions fit available shifts, and every decision can be explained with a retained frame and rule.
Management takeaway
The SMBSC case demonstrates a strong applied-AI formula: do not replace the expert; turn an occasional subjective check into continuous measurement with explicit thresholds and an exception queue. The neural network alone does not create value. The complete chain does: camera, load identifier, numerical score, business rule, human decision, and audit trail.
Start with one visible defect and four weeks of shadow mode. Vnutrik may already be ready to inspect every beet with a magnifying glass, but management still needs to confirm that the camera points to the right place, thresholds are expressed in money, and a disputed load does not disappear between the model and ERP.