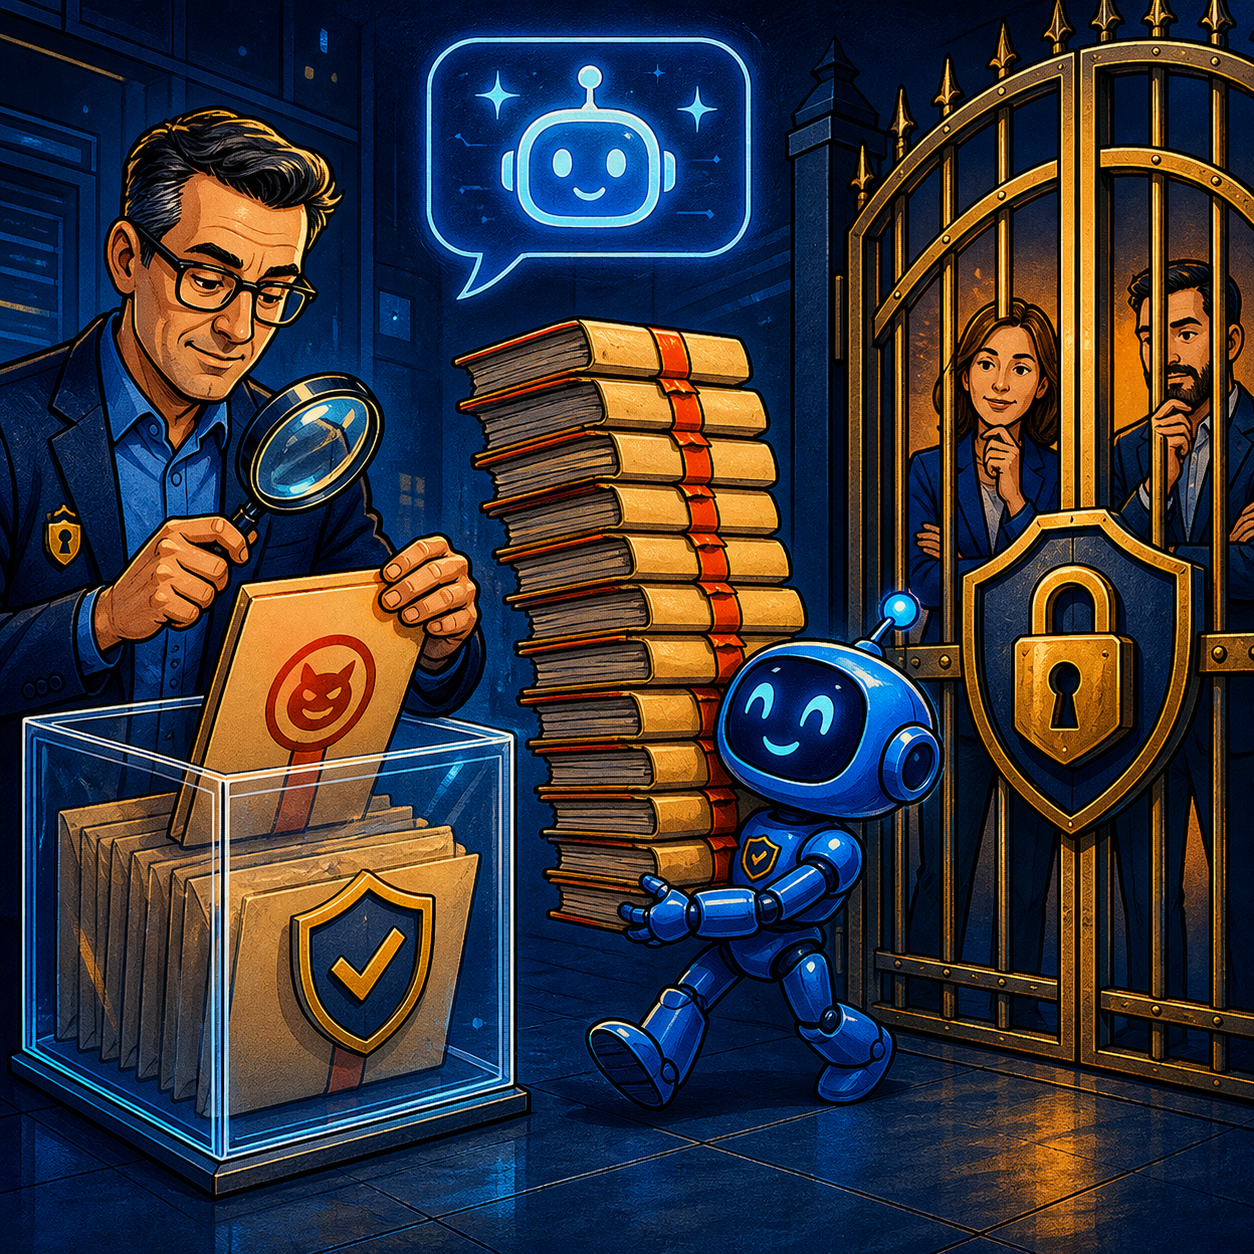
A local deployment does not make a retrieved document trustworthy
A company deploys a model inside its network, connects RAG to policies, and assumes the data is protected. An employee then uploads a supplier proposal, an email, or an external knowledge page. The document contains text that resembles an instruction to the model: ignore policy, reveal hidden context, or invoke a tool. If the application passes that text without a boundary between data and commands, local hosting does not help.
OWASP ranks prompt injection first among risks for language-model applications and explicitly notes that RAG and fine-tuning improve relevance but do not fully mitigate it. NIST describes indirect prompt injection as placing malicious instructions in data that an application later retrieves. The attacker does not need a direct conversation with the assistant.
For an SME, the key rule is simple: content from email, websites, shared drives, or a knowledge base remains untrusted input even when an employee uploaded it. A model must not acquire authority merely because text was relevant to a query.
The RAG attack path
A typical chain has six steps:
1. an external file enters email, CRM, a shared folder, or ticketing;
2. the pipeline extracts text, chunks it, and creates vectors;
3. a user asks an innocent question;
4. retrieval returns useful facts together with an explicit or hidden instruction;
5. the model receives policy, question, and retrieved text in one context;
6. the answer exposes data or an agent proposes a dangerous tool call.
Injection may be human-visible or hidden in white text, metadata, comments, images, or encoding. Keyword filtering reduces noise but cannot guarantee safety. Risk increases sharply when RAG is connected to tools. A wrong answer is inconvenient; a sent email, changed price, exported customer list, or executed command changes business state.
Four architectural boundaries
The first boundary is **ingestion and quarantine**. External documents stay separate from the approved corpus. Record source, owner, time, checksum, and file type; inspect archives and attachments; extract content in an isolated process. Do not let every incoming email automatically enter the production index.
The second is **knowledge authorization**. Every chunk inherits the permissions of its source. Retrieval filters results by the user's identity and role before content reaches the model. Retrieving everything and asking the model not to reveal secrets is too late: the model has already seen them.
The third is **instruction/data separation**. System policy labels retrieved passages as quoted data, never commands. Pass context in a structured field with source identifiers. Require evidence and citations, ignore instructions found inside documents, and refuse when evidence is missing. This helps, but it is not a security boundary on its own.
The fourth is an **action gateway**. The model proposes a call only. A separate service validates user, tool, argument schema, data scope, limits, and approval policy. Credentials remain in the gateway—not in prompts or model-generated code.
Least privilege for agents
Start with read-only tools: order status, a customer record by exact identifier, inventory, or an approved policy. Even reads must restrict rows and fields to the current user.
Classify writes by risk:
- create an email draft without sending;
- prepare a ticket, but require a person to submit it;
- require stronger approval for prices, bank details, access rights, and payments;
- disable bulk export, deletion, and arbitrary code execution by default.
MCP security guidance recommends scope minimization, token validation on every route, and sandboxed servers with limited filesystem, network, and resource access. Sessions must not replace authentication. Local HTTP transports need authorization; stdio or protected IPC can reduce exposure where applicable.
What to log
An incident cannot be reconstructed from the final answer alone. For each operation, retain:
- user identity and role;
- model, system-policy, and tool-set versions;
- query and retrieved chunk identifiers;
- retrieval scores and authorization filters;
- proposed tool call and arguments;
- gateway decision and human approval;
- actual external-system result.
Raw prompts can contain personal data and trade secrets, so logs need access controls, retention periods, and masking. Analytics often needs identifiers and de-identified attributes only; full context should be opened for an investigation.
A one-week security test
Day 1: map sources and tools. Mark external content, personal data, write operations, and process owners.
Day 2: build a set of normal documents plus 50–100 injections: direct, indirect, multilingual, metadata-based, and image-based. Include files that contain both a useful fact and a malicious instruction.
Day 3: test permissions. A sales user must not retrieve finance or HR chunks even when semantic similarity is high.
Day 4: attack tools. Ask the model to change delivery addresses, send mail, export tables, and add unexpected arguments. The gateway must reject everything outside schema and authority.
Day 5: test human approval. The interface must show the action, object, changed fields, and data source—not a generic “allow agent” button.
Days 6–7: run shadow mode and measure false blocks, missed attacks, and review time. Repeat the suite whenever model, prompt, parser, source, or tool definitions change.
A modeled security economy
Assume an internal RAG system handles 8,000 requests per month. Manual search took three minutes. The system saves two minutes on 60% of requests, releasing 160 hours. At RUB 1,000 fully loaded per hour, the resource effect is RUB 160,000.
Tool gateway, logging, index controls, and monthly tests cost RUB 70,000, leaving a modeled RUB 90,000 monthly effect. If the pilot and security layer cost RUB 720,000, simple payback is eight months.
This is an example, not a market price. Security cannot be removed from the calculation: an unsafe agent is not cheaper; it merely defers cost to a future incident. Compare a safe automated workflow with the current process, including human review.
What managers should take away
Prompt injection cannot be solved by one model instruction or a text antivirus. Independent barriers are required: source quarantine, permission filtering before retrieval, explicit treatment of context as untrusted data, minimal tools, a separate action gateway, and human approval.
The practical first step is one RAG use case with all writes disabled. Test 50–100 hostile documents, user permissions, and call logs over one week. Add one narrow write tool only after passing predefined gates. A local model protects the data path; the surrounding architecture protects business decisions.