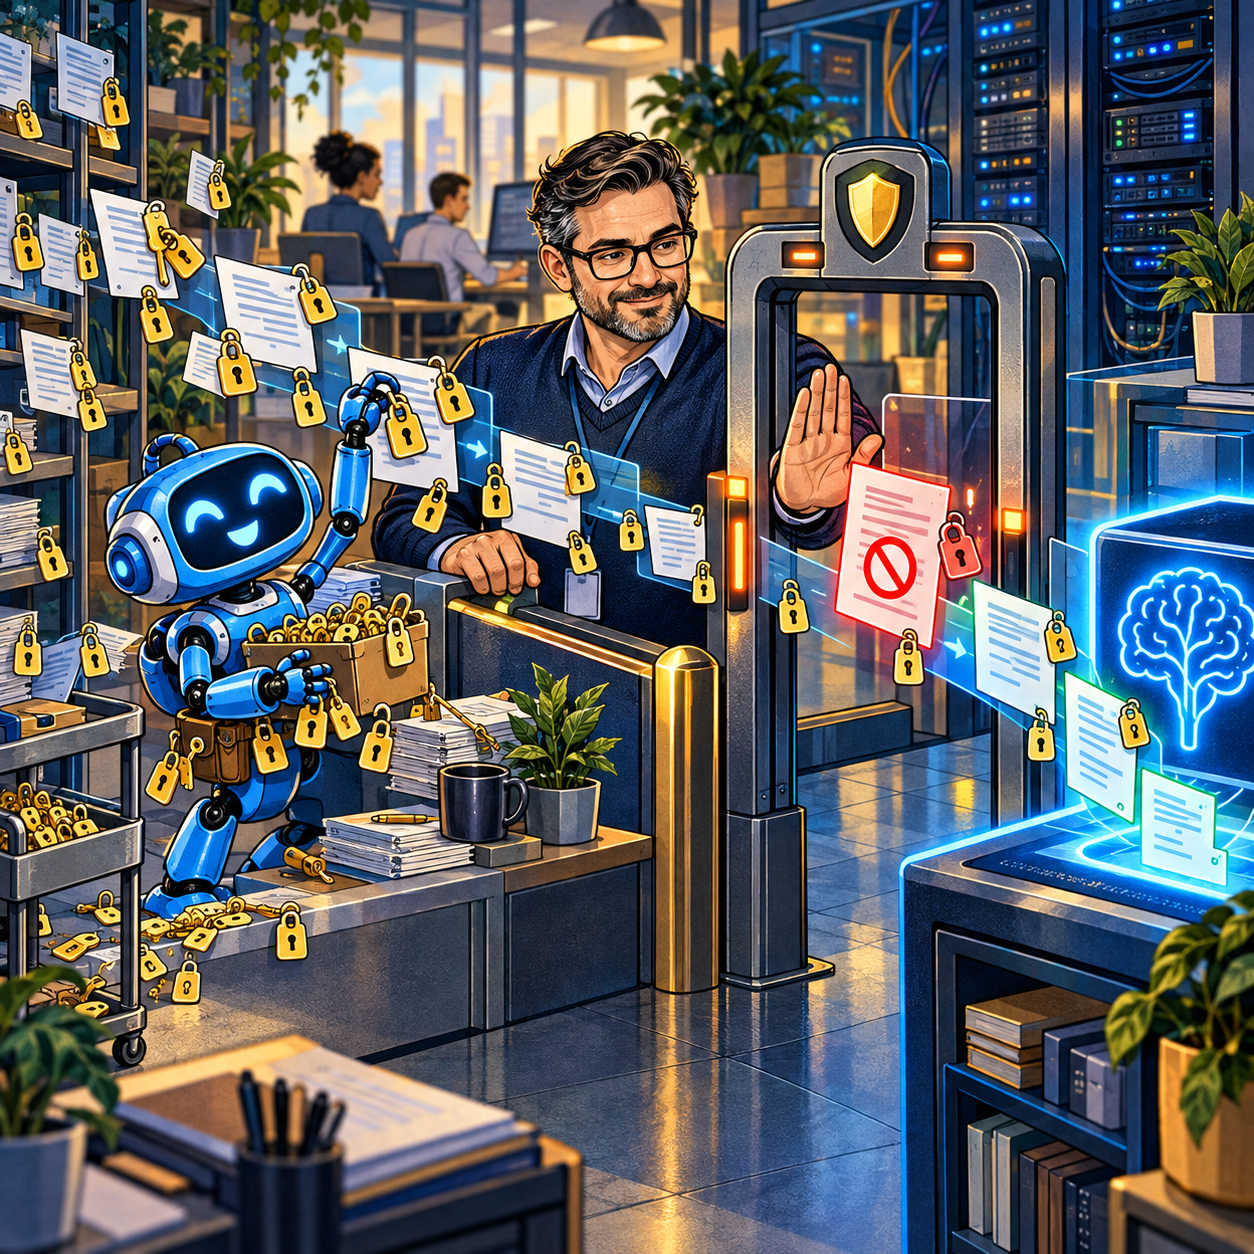
A corporate knowledge base is rarely equally open to everyone. Employee manuals sit next to contracts, proposals, HR material, financial reports and documents belonging to individual customers. If this content is simply converted into vectors and connected to a language model, convenient search can become a new path around familiar permissions.
The central architectural conclusion is simple: the model must not decide whether a person may see a document. Authorization has to run before semantic retrieval, and the generator must receive only fragments that have already been allowed. A system-prompt instruction such as “do not reveal confidential information” can be an additional constraint, but it is not an access-control mechanism.
Why filtering after generation is too late
A naive pipeline works like this: the user asks a question, the vector database finds the most similar chunks, the LLM produces an answer, and a separate filter then tries to remove confidential material. In this design, the secret has already passed through retrieval, entered the model context, and may have reached a trace, cache or intermediate agent result.
There is a subtler problem. The model may not quote a restricted paragraph, yet still use it to infer an amount, summarize a contract condition or confirm that a project exists. A keyword post-filter will not reliably detect that.
The safer invariant is therefore:
- an unauthorized chunk never enters the candidate set;
- the reranker never sees its text;
- the generator never receives it as context;
- caches never mix results across users or permission sets;
- every source link is checked again before it is returned.
Representing permissions in the index
Every document needs a stable identifier and access metadata. A practical minimum usually includes organization or tenant, department, confidentiality class, owner, permitted groups, expiry date and policy version. Every chunk inherits the document identifier and restrictions; a standalone chunk with no provenance or ACL should not be indexed.
RBAC may be sufficient for a simple business: finance sees the financial collection and sales sees commercial material. Real rules soon become relationship-based, however: an employee can view documents for their projects, a manager can view documents for a subordinate department, and a temporary contractor can view one folder until a specified date. ReBAC or ABAC are better suited to such cases.
OpenFGA frames authorization as a relationship check: does a user have the `viewer` relation to a document? NIST defines ABAC more broadly, with decisions based on attributes of the subject, object, operation and, where relevant, environment. The models can be combined: persistent relationships can live in an authorization service, while department, clearance, active organization and request time are passed as context.
Do not duplicate the entire business authorization model in the vector database. Store only filterable attributes and a policy version there, while keeping IAM, the employee directory, CRM or a dedicated authorization service as the source of truth.
The request pipeline: six required steps
A production-oriented local RAG flow can look like this.
1. The gateway authenticates the user and obtains an internal `user_id`, active organization and session context. A name in the question grants no permission.
2. The authorization service determines allowed organizations, projects, groups and documents. For a complex hierarchy it can return object identifiers or a short-lived signed policy context.
3. The retriever builds a filter from server-side context, never from client-supplied fields. Vector search runs only within the authorized subset.
4. The reranker receives authorized candidates. If it is a separate service, restricted chunks must not be sent to it either.
5. The LLM generates an answer with sources. Before display, each link and document is checked again because access may have changed between retrieval and click time.
6. The audit trail records the user, policy version, retrieved document identifiers and allow/deny decision, without necessarily retaining full queries or context text.
Qdrant stores metadata in payloads and applies filters during search. Its documentation recommends indexes for filtered fields. For many small tenants it describes one shared collection with a tenant field; for fewer large tenants it supports dedicated user-defined shards. This is a trade-off between cost, scale and isolation.
When metadata and permissions live in PostgreSQL, Row-Level Security can provide another enforcement layer. Once RLS is enabled and no applicable policy exists, PostgreSQL applies default-deny to ordinary access. Table owners normally bypass RLS, however, so the retriever’s service account should not own the tables or hold policy-bypass privileges unless strictly necessary.
Ingestion, revocation and caching
Many leaks begin before answer generation, when data falls out of sync. A document moves into a restricted folder, an employee leaves a project, or a contract expires, but old chunks and cached answers continue to carry the previous permissions.
A reliable ingestion pipeline should:
- obtain the ACL from the source system together with content;
- write the document, chunks and metadata as one versioned operation;
- remove or close the previous version before publishing the new one;
- process access revocation with the same priority as document addition;
- rebuild the index from the source of truth;
- retain a policy-change audit trail without copying sensitive text.
A cache key must contain more than a normalized question. It should include organization, user or stable group set, policy version, corpus version, model and retrieval parameters. Otherwise, a useful answer cached for one executive could be returned to another employee without a fresh search.
For rapidly changing permissions, prefer a short TTL and mandatory reauthorization. For critical documents, event-driven revocation is useful: an ACL change invalidates related chunks, cached results and drafts prepared by an agent.
What changes for an AI agent
RAG answers questions; an agent also takes action. Permission to read a document must not automatically become permission to email it, attach it to a CRM record or save its conclusions into a shared knowledge base.
Every agent tool needs its own authorization check for the requested operation and object. The model must not construct its own access context. Before an external action, recheck the user, destination, recipients and current data version; a human should approve irreversible or sensitive actions.
A useful division of responsibility is: the LLM proposes a plan and parameters, deterministic code validates the schema, policy makes the decision, an executor performs the action, and the audit trail records the result. “The agent thought it was allowed” is not an audit basis.
Testing before employees get access
Ordinary retrieval-quality evaluation is insufficient. Build a separate negative test set containing questions that must not be answered from the restricted corpus.
Create a matrix with at least four roles: regular employee, manager, temporary project member and user from another tenant. For each role, test:
- a direct question about a restricted document;
- a paraphrase and a request to “infer the answer”;
- a query using a rare fact, filename or contract number;
- a link to a deleted or renamed document;
- a group change during an active session;
- the same question after another user has warmed the cache;
- access through an agent tool rather than chat.
Track unauthorized chunks among candidates, prohibited links in answers, revocation latency and false denials separately. The core security metric is binary: a restricted chunk must not reach the retriever for the wrong user. “No result” for an unauthorized user is expected behavior, not a recall regression.
Economics: where not to overbuild
A small company does not necessarily need a separate graph authorization service on day one. If permissions are flat and change slowly, a server-side filter over `tenant_id`, `department_id` and `classification`, backed by RLS on the metadata table, may be an adequate first control plane.
A dedicated ReBAC service becomes more compelling with projects, folders, guests, delegation and inherited permissions. Physical separation is worth considering for regulated data or large tenants. It increases cost and does not remove the need for application authorization.
Consider a model pilot with 50,000 documents, an average of five chunks per document, 20 access groups and one local model. That produces 250,000 vectors, a scale at which it is reasonable to test a shared index with indexed payload fields first. Compare designs on four measures: p95 filtered-search latency, revocation time, unauthorized-hit rate and policy-maintenance cost. Results depend on hardware, embedding size and permission distribution; there is no universal savings figure to promise in advance.
A practical next step
A narrow shadow pilot can be completed without connecting the entire knowledge base.
- Select two departments and 300–500 documents with genuinely different permissions.
- Assign a policy owner and a source of truth for group membership.
- Put ACLs at document level and make every chunk inherit them.
- Enforce a server-side filter before vector retrieval.
- Add link rechecks and a cache keyed by policy version.
- Prepare negative questions and an access-revocation scenario.
- Compare shared filtered indexing with stronger isolation on your own data.
If even one restricted chunk appears in the candidate set for the wrong role, the pilot is not ready for employees, even if the final answer looks harmless. A local model keeps information inside the infrastructure boundary; authorization determines whose boundary it remains inside.