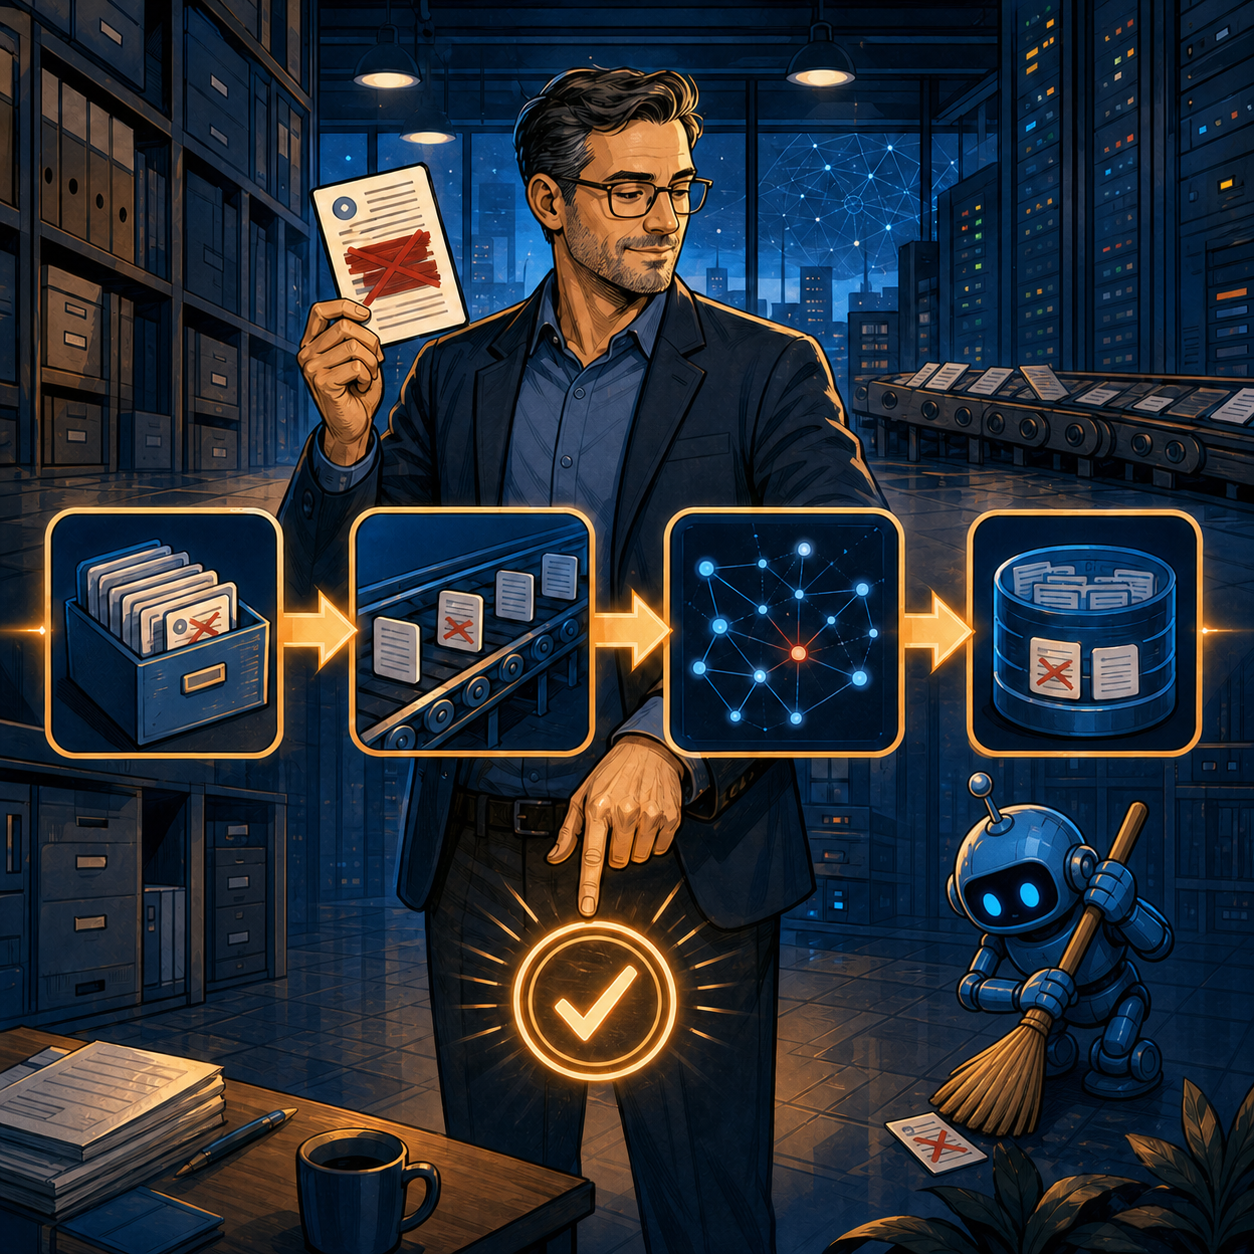
Why deleting the file is not enough
In a production RAG system, one document quickly becomes several derived objects. The source lives in object storage, parsed text in an intermediate database, chunks in an indexing queue, embeddings and metadata in a vector index, and finished answers in a cache. Logs, backups and failed jobs waiting for retry add more copies.
Deleting only the source PDF leaves its chunks searchable. Clearing the index alone allows an old job to insert them again. Deletion is therefore not a button in one interface but a distributed business process with an identifier, states and verification.
This matters to smaller businesses beyond formal data-subject requests. A terminated contract, an incorrect policy version, a confidential price list, a withdrawn proposal or a file uploaded to the wrong customer project all require reliable removal.
Start with a stable document_id
Deletion cannot be proven if document parts are linked only by filename. Names change, collide across customers and disappear during OCR. Every ingested source needs a stable `document_id`; each chunk needs a derived `chunk_id`, for example a hash of document, version and position.
The identifiers must travel through:
- the source registry and object store;
- OCR or parsing output;
- queues and job tables;
- each vector payload;
- search indexes;
- response caches and source provenance;
- the operations audit trail.
Without that lineage, teams rely on text matching. It misses reformatted chunks and can delete unrelated documents containing similar language.
Deletion as a five-step saga
A practical design starts with a deletion registry. The API accepts `document_id`, reason, scope and an idempotency key. It immediately places the document in a `blocked` state so new reads and indexing are denied while physical cleanup continues.
The orchestrator then performs five steps:
1. Mark the source deleted and prevent creation of new indexing jobs.
2. Cancel pending and retrying jobs for that document.
3. Delete chunks from full-text and vector indexes with exact filters.
4. Invalidate answers and semantic-cache entries whose provenance names the document.
5. Run verification searches and store a completion receipt.
Each step records status, object count and a short error. Repeating the same request continues the unfinished saga rather than creating a parallel deletion. This is the same idempotency principle used for payments and outbound messages.
An asynchronous acknowledgement is not success
Vector and search engines often execute bulk deletion asynchronously. Qdrant supports deleting points by filter and waiting for the operation. OpenSearch `delete_by_query` may return a task ID; its documentation covers task monitoring, version conflicts, partial failures and refresh behavior.
HTTP 200 or `acknowledged` may therefore mean only that the command was accepted. The orchestrator must wait for a terminal state, inspect failures and verify that the change is visible to readers. For OpenSearch this includes refresh semantics; for any engine it includes a control query for `document_id`.
Wildcard deletion is risky. Filters should include tenant, collection and exact document identifier. A useful dry run counts expected chunks and stops if the number differs sharply from the indexing registry.
Tombstones prevent resurrection
In a streaming design, deletion must propagate as an event. Debezium for PostgreSQL emits a DELETE event followed by a tombstone with the same key and a null value so log-compacted systems can remove prior state.
A RAG pipeline benefits from its own tombstone registry containing document ID, deletion version, time and scope. Every worker checks it before an upsert. Even if an old message is delayed or a job returns from a dead-letter queue, the document cannot be recreated.
The tombstone should contain minimal metadata, never the deleted content. Retain it longer than the maximum lifetime of queues, retries and import packages; otherwise an ancient message may resurrect a record after the guard expires.
Caches, logs and backups
Finished-answer caches need source lineage. If an entry stores only prompt and answer, targeted invalidation is impossible. Store the contributing document IDs or a knowledge-base version and delete dependent entries.
Operational logs should not contain full model context by default. Hashes, identifiers, metrics and reason codes are usually sufficient. If content is logged, that store must appear in the data map and deletion procedure.
Backups need an explicit policy. Immediately rewriting every backup is often impractical. A realistic design excludes deleted data during restore through the tombstone ledger, limits backup retention and tests restore in isolation. The deletion receipt should state what left active systems immediately and what expires according to retention.
Proving completion
Verification searches more than the original text. The system checks:
- the source registry by `document_id`;
- queues, retries and dead-letter storage;
- vector and full-text indexes using exact filters;
- dependent cache entries;
- a test RAG query containing a distinctive phrase;
- deleted chunk counts against the indexing registry.
The result is a concise receipt: operation ID, time, affected stores, expected and actual object counts, errors and backup expiry. The deleted content itself is not copied into the receipt.
Sensitive workflows may require a two-person rule: one employee initiates deletion and another confirms scope. This also protects against accidentally deleting an entire customer collection.
Economics and scope
Consider a model pilot: five stores, 20 removals per month and 15 minutes of manual verification each. That is 25 hours per year. At a notional fully loaded cost of 2,000 rubles per hour, direct labor is 50,000 rubles, before incident costs. Automation makes sense when build and maintenance cost less while reducing error risk.
Do not build a platform for two deletions a year. The minimum viable control is a stable document ID, a re-indexing block, filtered index deletion, cache invalidation and a verification query. The state registry can live in the same transactional database as indexing jobs.
RAG deletion must also be distinguished from removing knowledge from model weights. If the document was external context only, derived-store cleanup is sufficient. If it was used for fine-tuning, the problem becomes machine unlearning or retraining and needs a separate decision.
What management should do
Ask the team to trace one test document through source storage, chunks, embeddings, answers and logs. Delete it in a non-production environment, deliberately delay an old job, and verify that the job cannot resurrect the data.
The readiness gate is simple: the document stops participating in answers immediately after blocking, every active copy is removed with confirmation, and restore or redelivery does not bring it back. Only then does the Delete button represent a process rather than a hope.