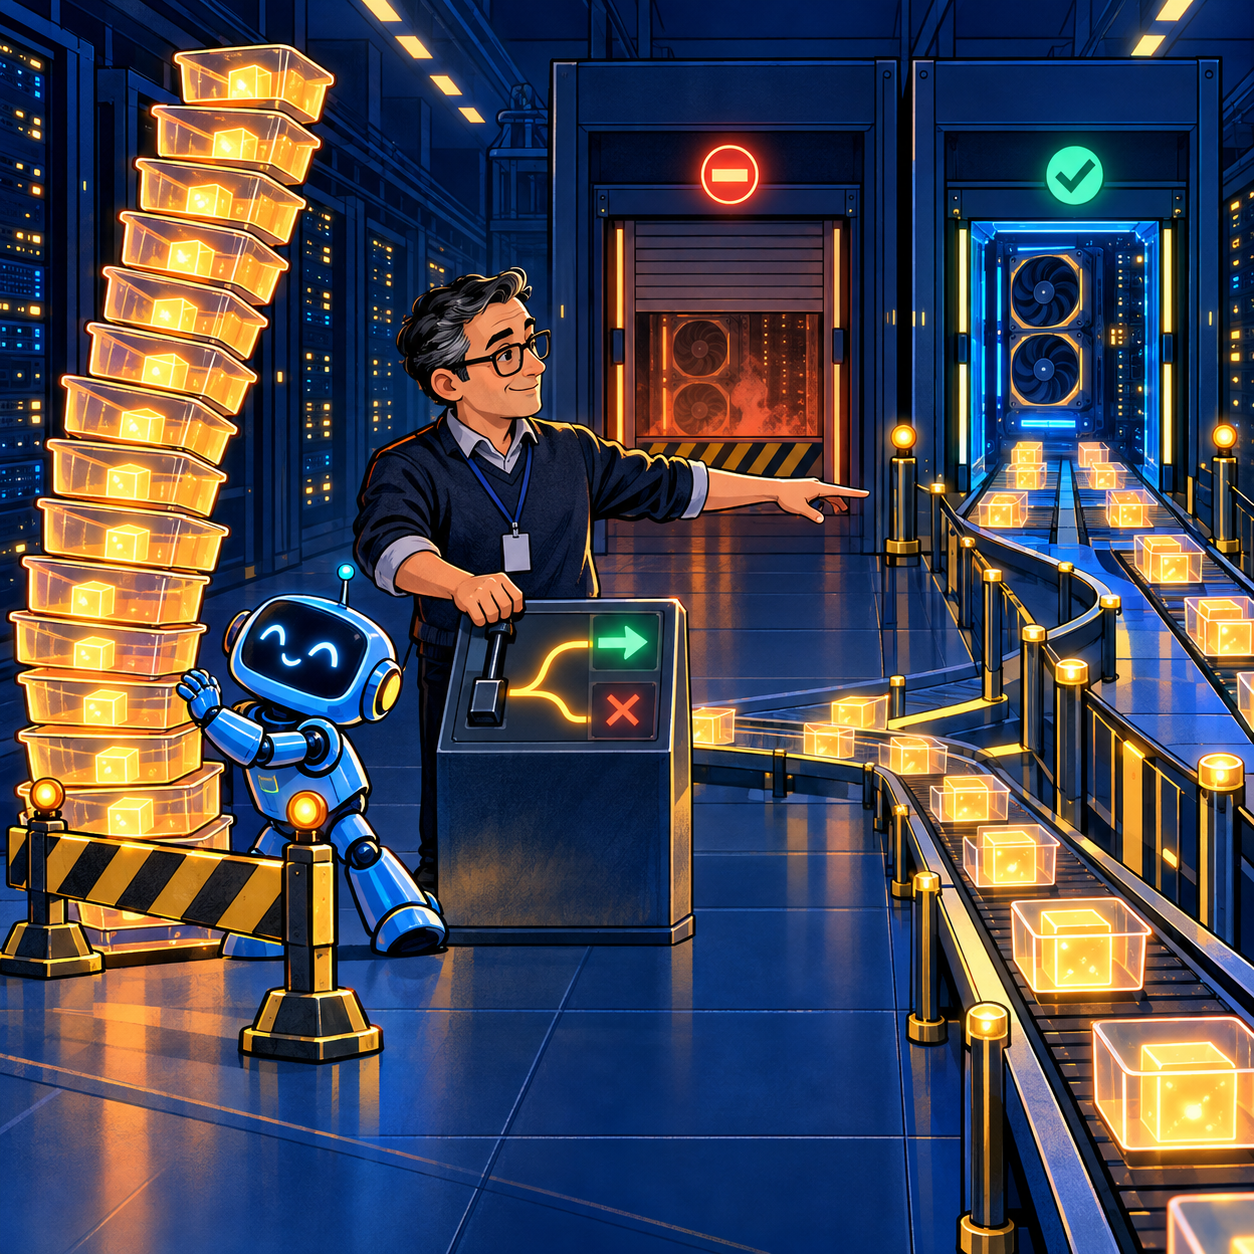
Why “the process is alive” does not mean “the model is ready”
A local LLM can pass a port check while being unable to accept new work: weights may still be loading, GPU memory may be saturated by the KV cache, the queue may be growing, one replica may be stuck, or model storage may be temporarily unavailable. Users see the same outcome—waiting, timeout or error—but the distinction is critical to the orchestrator.
If every open port is treated as healthy, the load balancer keeps sending traffic to the overloaded replica. If every slowdown triggers a restart, the remaining instances receive even more requests. A small queue then becomes a team exercise in creating a cascading failure.
A resilient deployment separates three questions:
- has the server started and loaded the model;
- can the process continue to make progress;
- is it ready to accept a new request now.
Kubernetes calls these startup, liveness and readiness probes. A startup probe gives a heavy service time to load weights. Liveness is for conditions that require a restart, such as a deadlock. Readiness temporarily removes an instance from load balancing without killing it. Kubernetes documentation explicitly warns that a poorly designed liveness probe under load can cause cascading restarts.
Architecture with a controlled entrance
A minimally resilient path looks like this:
1. The client calls a shared gateway rather than a model server directly.
2. The gateway validates request size, permissions, deadline and operation identifier.
3. Admission control chooses whether to accept, place the request in a bounded queue, switch it to asynchronous execution or reject quickly.
4. The load balancer selects only ready replicas.
5. Model servers publish queue, KV-cache, TTFT and error metrics.
6. When thresholds are crossed, a circuit breaker stops work from accumulating faster than it can be processed.
7. Prolonged degradation activates a pre-approved fallback mode.
The most important component is not the second GPU but a gateway with a finite queue. An infinite queue does not improve availability. It turns a fast, explicit rejection into a slow and expensive timeout.
Envoy documents limits for active connections, pending requests, outstanding requests and retries. These mechanisms act as network-level circuit breakers. For local LLMs, pending-request limits and retry budgets are particularly useful: retries must not double load during an incident.
Signals for readiness
A readiness check should be inexpensive and reflect the ability to accept new work. An HTTP 200 from the process is insufficient.
A practical readiness policy may consider:
- the model is fully loaded and has passed a small control inference;
- pending requests remain below a threshold;
- KV-cache usage is below a critical level;
- no recent series of memory-allocation failures exists;
- required local dependencies are available;
- the replica is not draining;
- GPU temperature and hardware errors do not require node removal.
vLLM publishes Prometheus metrics through `/metrics`, including running and waiting requests, KV-cache usage, queue time, time to first token, inter-token latency, preemptions and request outcomes. These are more useful for traffic decisions than generic GPU utilisation.
Readiness does not need to change on a single instantaneous value. Two thresholds and a time window reduce flapping: remove a replica after a sustained queue increase and return it only after load has fallen. Otherwise, the instance changes state faster than an operator can open the dashboard.
Liveness should be simpler and stricter. A high queue means “do not accept new traffic,” not necessarily “restart the process.” Restart only when the server stops making progress, fails internal diagnostics or reaches a confirmed unrecoverable state.
What to do when capacity is exhausted
The system needs several predefined overload responses:
- fast HTTP 429 or 503 with safe retry guidance;
- a bounded queue with a deadline;
- an asynchronous job with an identifier and status endpoint;
- reduced context or generation length for non-critical scenarios;
- a smaller local model for approved task classes;
- a deterministic template without generation;
- human escalation.
The choice depends on the process. An email draft can wait, knowledge search may return a shorter answer, and a payment action must not silently change models or run twice. A fallback must preserve permissions, audit logging and business constraints.
Automatic failover to an external cloud is not neutral. It changes the data boundary, contractual conditions and sometimes model behaviour. Such routing must be an explicitly approved policy for a particular data class, not an engineering surprise at three in the morning.
Why retries are more dangerous than they appear
When a client receives a timeout, it often submits the request again. A proxy may do the same. If the first operation is still running, load doubles. For generation this wastes tokens; for an agent with tools it can duplicate an email, ticket or CRM update.
The design therefore needs:
- a stable idempotency key for each logical operation;
- bounded retry count and a total deadline;
- randomised backoff between attempts;
- no automatic retry after a side effect has begun;
- an operation ledger accessible through a separate status request;
- a gateway-level retry budget.
Only proven-safe operations should be retried. “Try again” is friendly interface copy and suspicious accounting logic.
Two replicas do not always provide high availability
If both replicas sit on one GPU node, share a power source and load weights from one disk, their failure isolation is limited. If they serve different model or tokenizer versions, behaviour becomes unpredictable.
Validate:
- separate nodes or at least independent GPUs;
- pinned and verified model artifacts;
- identical tokenizers, templates and parameters;
- weight availability without public internet access;
- power and network separation where downtime is expensive;
- warm-up before a new replica receives traffic;
- draining before an old replica stops;
- enough remaining capacity after one node is lost.
The final item is commonly forgotten. Two replicas running at 70% do not provide N+1 capacity. After a failure, one receives 140% of demand and follows its colleague heroically into the incident report.
Model economics of availability
Suppose a local assistant processes 1,000 requests per business day and one unavailable hour creates 120 manual tasks of eight minutes each. At an internal labour cost of RUB 800 per hour, downtime costs about RUB 12,800 per hour, excluding missed deadlines.
A standby replica costing RUB 80,000 per month pays back only if it prevents more than 6.25 hours of this loss. However, if a gateway, bounded queue and correct readiness policy reduce downtime from four hours to thirty minutes without a second full GPU, architecture discipline is more economical than hardware.
This is an illustrative model. Replace the assumptions with the actual number of affected employees, delay cost and share of processes that can continue manually. The cost per hour may be much higher in sales or production and lower for internal drafting.
A one-week resilience pilot
1. Define target p95 TTFT, maximum queue and tolerated outage.
2. Separate startup, readiness and liveness; do not reuse one endpoint for three meanings.
3. Bound pending requests and retries at the gateway.
4. Configure replica warm-up and draining.
5. Define a fallback mode for each task class.
6. Inject controlled failures: slow loading, full KV cache, lost GPU node, unavailable weights and a burst of long prompts.
7. Verify that important operations are not duplicated and restricted data never leaves the approved boundary.
8. Measure recovery time and lost accepted outcomes.
What success looks like
A resilient service does not have to answer everything. It must predictably accept the work it can handle, limit excess demand quickly, preserve important operations and recover without a chain reaction.
For an SME, the sensible sequence is metrics and a bounded queue first, readiness and circuit breakers second, and a standby replica third. Otherwise Vnutrik receives a second server merely to build a second queue on it. The intern is delighted; the SLA is less enthusiastic.