“Local” describes where processing happens, not who is allowed in
A local model can solve an important problem: requests may be processed on company equipment instead of being sent to an external AI API. But “local” describes where computation takes place, not who may contact the server. If the service is reachable from the office network, it is an internal network service with trust boundaries of its own.
Ollama’s documentation says that its API listens on `127.0.0.1:11434` by default. To make it reachable over a network, the bind address can be changed through `OLLAMA_HOST`. That is useful when a dedicated server must serve several users, but changing the bind does not by itself add authentication, roles, or audit logging. The local API examples omit an authorization key, so access to the port should be treated as a privilege to be constrained by network and application controls.
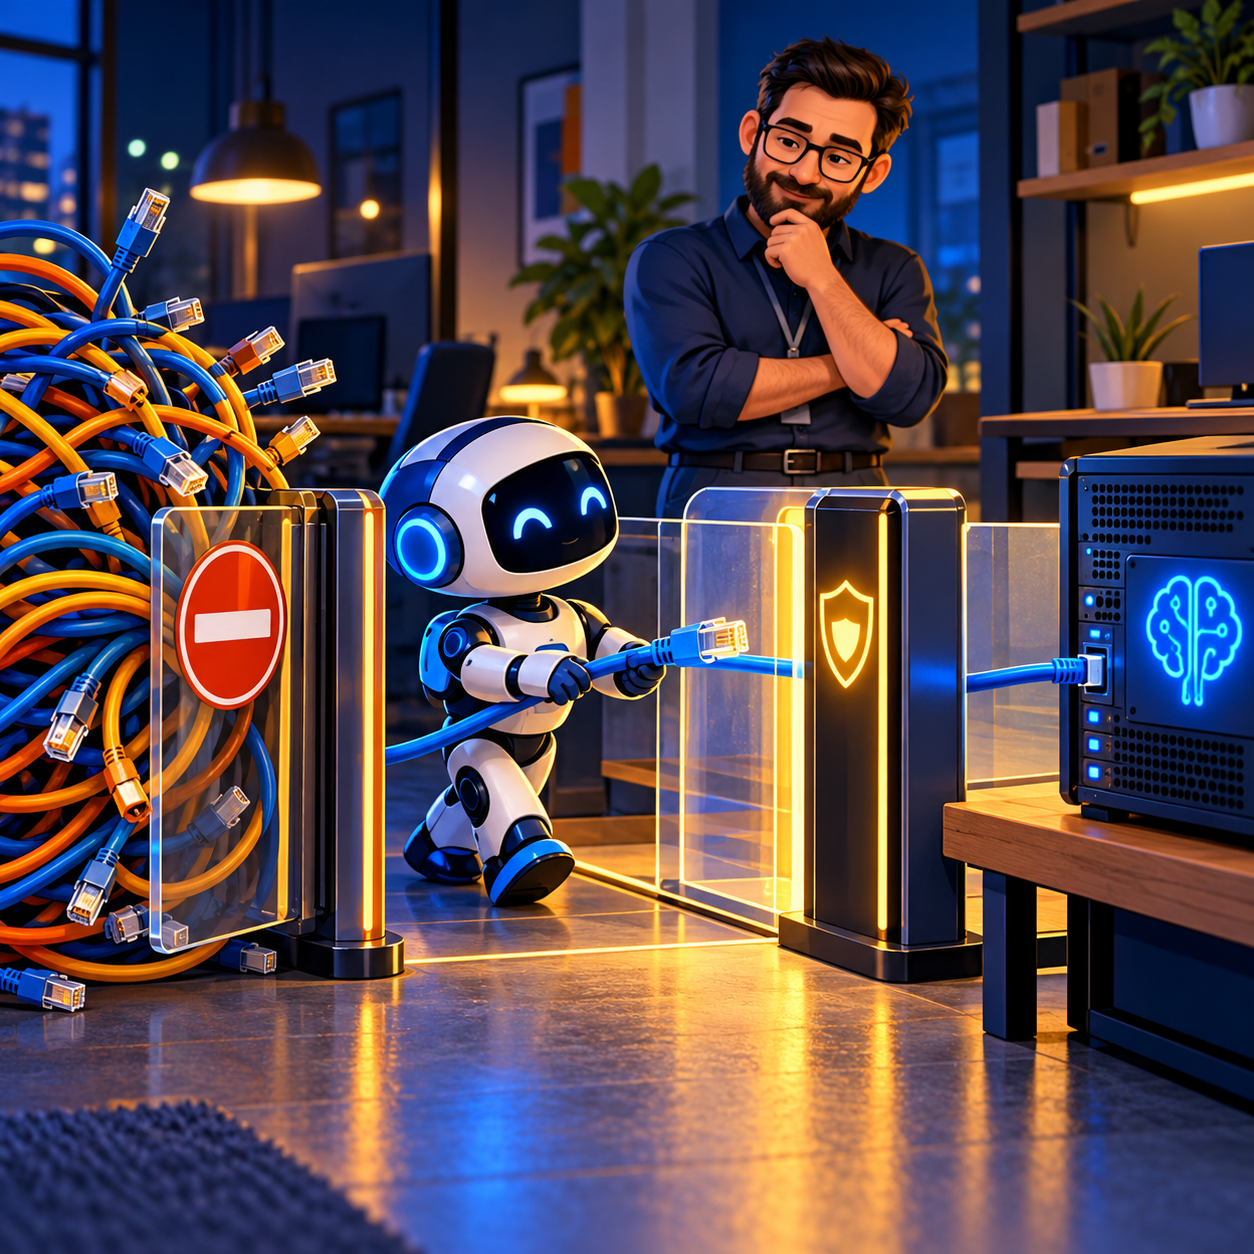
Imagine a robot intern who meant to connect one workstation to the model but brought the entire office cable bundle into the server room. It is not malicious; it simply has not learned the difference between “let this service in” and “let everyone who finds a socket in.”
First decide who actually needs direct access
For a single user or prototype, keep the API on loopback (`127.0.0.1`) and call it from the same computer. Do not change `OLLAMA_HOST` to `0.0.0.0` just because it makes a connection test easier. That bind listens on all IPv4 interfaces; actual reachability then depends on the firewall, routing, and container configuration.
If employees need a shared chat interface, they do not necessarily need direct access to the model API. Keep Ollama on a separate host and put an access layer in front of the user interface: a corporate VPN, an authenticating reverse proxy, or a managed gateway with TLS. Open WebUI’s hardening guide recommends placing the interface behind a VPN, zero-trust proxy, or reverse proxy with authentication and IP allowlisting; it should not be exposed directly to the internet without an additional control layer.
A minimal design for a small office
A practical first version looks like this:
- **Model server** sits in a separate network segment or on a dedicated host. The Ollama port is not published to the internet and cannot be reached from guest Wi-Fi.
- **User entry point** is one known URL with TLS and identity checks. If the company already has a VPN or identity gateway, use it instead of adding another public entry point.
- **Firewall rules** allow connections only from the specific proxy or backend service to the model API. Workstations and other VLANs do not need a direct route to the inference port.
- **Service credentials** are separated by application and person; permissions are limited to what the workflow needs. If the gateway cannot check permissions, do not treat network isolation alone as full authorization.
- **Logs** record the user or service, time, access outcome, and request volume. Record prompt content only when there is a clear purpose, a retention policy, and protection for those logs.
This does not have to mean a complex zero-trust platform. For a small company, the point is simpler: an internal IP address is not proof of identity, and access to one resource should not automatically open neighboring resources. That shift—from trusting network location to focusing on identity and individual resources—is described in NIST SP 800-207.
When a reverse proxy helps—and what it does not do automatically
A reverse proxy is useful as a single entry point: it can terminate TLS, check credentials, limit request rates, and write access logs. But a plain `proxy_pass` only forwards HTTP requests. If authentication is not configured, the proxy does not magically secure the API. Also confirm that the direct Ollama port is unreachable around the proxy; otherwise a user or device can bypass the controls at the front door.
Browser interfaces create another common false sense of security. Restricting CORS with `OLLAMA_ORIGINS` controls which browser origins may make cross-origin requests. It does not replace authentication or a network firewall: a non-browser client is not required to follow the browser’s CORS policy.
Separate inbound and outbound traffic. A service may need internet access for updates or model downloads, but that does not mean the inference port should be exposed to the outside. Set separate rules for updates and for user requests.
Checks to run before a pilot
Before loading internal documents, run a short technical test with the person responsible for IT:
1. On the server itself, verify the intended listening address and make a local API call.
2. From an ordinary workstation, guest Wi-Fi, and an external network, verify that the direct port is reachable only where the design allows it.
3. Test the user path through the proxy: an unauthenticated request is rejected; an authenticated request reaches the model; the log records the subject and outcome.
4. Confirm that stopping the proxy closes user access rather than leaving an open bypass port.
5. Change the test account’s access rule and confirm that revocation stops new requests.
Do not test only from an administrator’s computer: it often has routes and permissions that ordinary employees do not. And do not send real personal or commercial data during a network test; a synthetic request is enough.
Trade-offs and cost
A stricter design adds work: DNS and certificate setup, proxy or VPN support, account management, updates, monitoring, and access recovery. That may be unnecessary for one standalone workstation. For several departments, compare cost not with a “free local API” but with IT support hours, the risk of accidental access, and service-availability requirements.
Local execution also does not guarantee that data can never leave the environment. Check the product mode and cloud features, network routes, plugins, logs, backups, and integrations. If a cloud model or external tool is part of the architecture, separate requests may be sent there.
What to do this week
Make a one-page table: who calls the model, from where, through which entry point, what data is sent, and who can revoke access. Start with loopback for a single-user workflow; for shared access, choose an existing corporate gateway, block direct access to the port with a firewall, and test the user path with an ordinary account.
That way, local AI stays local in its processing—and does not become open to everyone just because all the cables ended up in one rack.