Start with completed calls, not a live voice bot
Many small and mid-sized businesses already have call recordings, yet the useful information remains trapped inside audio. Salespeople manually copy commitments into the CRM, managers sample a few recordings, and rejection reasons are reconstructed from memory. Local AI can turn a recording into a transcript, a concise summary, and a draft CRM record without sending the original audio to an external service.
The safest first use case is batch processing of completed calls. It is simpler than a live voice bot: a delay of a few minutes is usually acceptable, an error does not disrupt the conversation, and an employee can review the result before anything is written to the CRM. The company also gains representative data for evaluating speech recognition on its own telephony.
Do not promise perfect understanding. Automatic speech recognition fails on noise, overlapping speech, names, product codes, and domain terminology. The Whisper model card explicitly warns about uneven quality across languages and accents, repetitions, and text that was never spoken. The architecture must therefore link every business conclusion to a recording segment and be able to reject uncertain output.
The data boundary begins in telephony
The first integration is not an LLM. It is an event from the PBX or contact-center platform. For each completed call, the system needs a stable identifier, an audio-object reference, and a small set of metadata: time, duration, direction, internal extension, and a deal or ticket ID when available.
Keep the source recording unchanged in protected object storage. Create a working copy in the format and sampling rate required by the ASR stack. If telephony supplies each participant on a separate channel, do not mix those channels prematurely. Channel separation is the most reliable evidence of who spoke. Diarization is primarily needed for mono recordings and should not be treated as proof of a person’s identity.
Before a pilot, the process owner should work with legal counsel or the data-protection owner to establish the legal basis, notice, purpose, retention, access roles, and deletion procedure. A recording, phone number, name, and conversation content may include personal data. Local deployment reduces the number of external recipients, but it does not make the processing lawful or secure by itself.
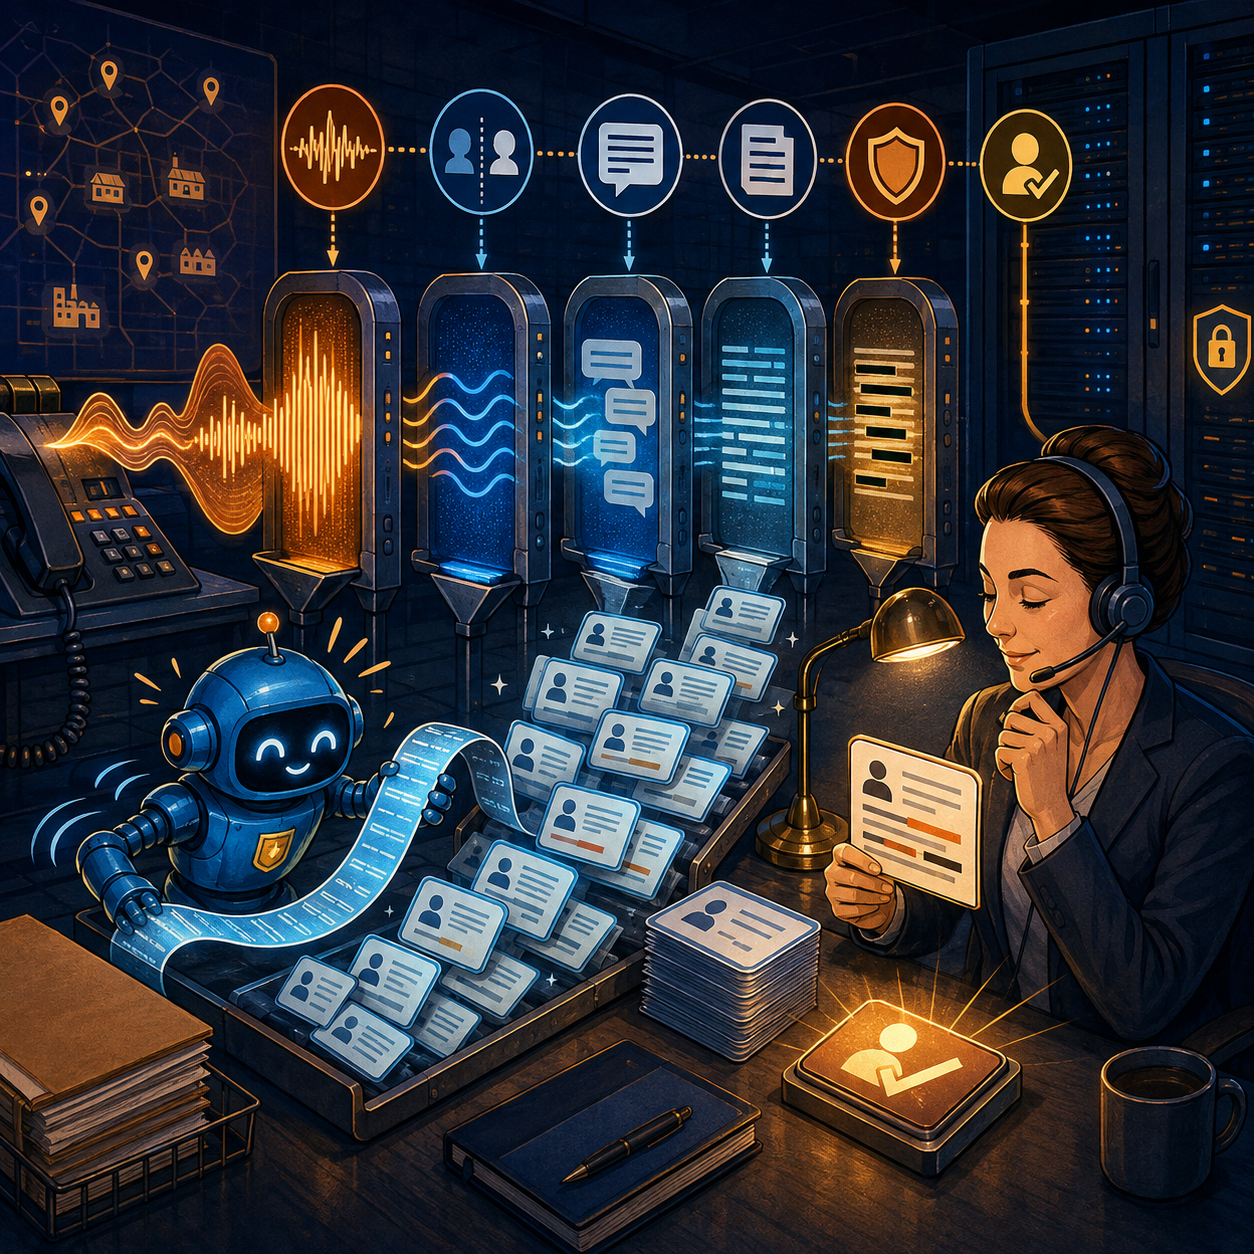
A practical nine-stage pipeline
A production-oriented flow is:
1. The PBX publishes a call-completed event.
2. An intake service validates file type, duration, checksum, and business-object linkage.
3. A decoder creates a working audio copy without changing the original.
4. Voice Activity Detection finds speech intervals and long pauses.
5. ASR transcribes speech and returns timestamps.
6. For mono audio, a separate module assigns turns to anonymous speakers.
7. A normalizer applies product, surname, and abbreviation dictionaries while preserving the original hypothesis.
8. A local LLM produces a structured draft summary with timestamp evidence.
9. An employee approves or corrects the record, after which a deterministic executor updates the CRM.
Each stage needs its own status and component version. If processing stops, the job resumes from the last confirmed checkpoint. An idempotency key can combine the call ID, audio checksum, and pipeline version. A duplicate PBX event then cannot create a second CRM note.
VAD saves compute but must not remove meaning
Voice Activity Detection separates speech from silence and avoids sending long pauses through ASR. Silero VAD is one local option; its official repository documents 8 kHz and 16 kHz inputs, PyTorch and ONNX runtimes, and an MIT license.
Test thresholds on telephone audio with hold music, quiet answers, and interruptions. Aggressive settings cut words and numbers; permissive settings expand the queue. Keep context margins around speech and preserve the source so segmentation can be recomputed.
Choose ASR on your calls, not on a generic leaderboard
Whisper is a convenient starting point for a local prototype. The official project publishes code and weights under MIT, several model sizes, multilingual recognition, and timestamps. Its memory and relative-speed figures are approximate; real performance depends on language, speech, and hardware.
Choose the model on the company’s own corpus. Correct product names, amounts, dates, and commitments matter more than an average public-dataset score. Return timestamped segments and quality signals. A glossary may guide decoding or transparent post-processing, but it must not silently overwrite the original hypothesis.
Diarization says when a speaker talked, not who the person is
When channels are not separated, diarization groups intervals by anonymous speaker. pyannote.audio supports local execution. For Community-1, the project requires accepting conditions and using a Hugging Face token for download; stored files can then run locally. Review code and checkpoint terms separately.
A `SPEAKER_00` label does not prove identity. Establish roles from channels, metadata, or human review. If a general summary is enough, diarization may not justify the complexity. If commitments must be assigned to each party, measure attribution errors on your own corpus.
The LLM receives text, not permission to write to the CRM
After ASR, send the model structured segments containing start and end time, anonymous speaker, text, a quality signal, and a reference to the audio. The model returns a strict object such as:
- topic and call outcome;
- customer need;
- objections;
- commitments by each party;
- next actions, owner, and due date;
- facts proposed for CRM fields;
- evidence timestamps;
- uncertainty and reasons for manual review.
Deterministic code validates schema, allowed values, and dates. No field is written automatically when it lacks a supporting segment or falls below the chosen confidence threshold. During the first release, the LLM creates a draft and an employee explicitly approves it.
Do not ask ASR or an LLM to infer honesty, emotion, nationality, health, or personality. The Whisper model card warns against subjective classification and high-risk decisions. Extract observable facts instead: whether a date, price, agreement, or specific commitment was stated.
Isolate sensitive content
A local system only helps when the data discipline is sound: encrypted storage and access logs, dedicated service identities, network segmentation between telephony, compute, and the CRM gateway, verified model versions, and separate retention periods for audio, transcripts, and summaries. Deletion must find every derived artifact by call ID.
Technical logs only need job IDs, component versions, stage timing, and error codes. A full transcript in ordinary application logs creates another uncontrolled conversation database, so content logging should be disabled by default. Redact or de-identify records before downstream analytics that does not need full identifiers.
Size the compute with measured real-time factor
The key capacity metric is real-time factor (RTF): the number of compute minutes required for one minute of audio. If a 60-minute recording takes 15 minutes to process, RTF is 0.25. Measure this on the chosen model, call format, and actual server.
Consider a model calculation. A company receives 1,200 audio minutes per day and wants to clear the nightly batch in 240 minutes. At RTF 0.25, the workload needs 300 compute minutes, averaging 1.25 parallel streams. With headroom for peaks, retries, and diarization, that may mean two or three worker slots. This is not a hardware specification; it translates pilot measurements into capacity planning.
Total cost includes storage and backups, decoding, VAD, ASR, diarization, the LLM, integrations, human review, monitoring, and reprocessing. Review and operations often determine the cost of an accepted record more than the GPU does.
For low and unpredictable volume, an external API may cost less than an idle server. Local processing is most compelling when audio is sensitive, demand is steady, suitable infrastructure already exists, and the team is prepared to operate the whole pipeline rather than only the model.
Metrics that make a pilot useful
Word Error Rate is a standard ASR measure used in NIST evaluations, but WER alone is insufficient. A wrong preposition and a wrong amount have very different business costs.
Measure:
- WER or CER on a representative sample;
- accuracy for names, product codes, amounts, dates, and addresses;
- speaker-attribution and overlap errors;
- the share of conclusions with a correct timestamp;
- recall of commitments and next actions;
- records accepted unchanged and after a minor edit;
- human review minutes per accepted record;
- p95 delay from call completion to draft;
- jobs quarantined or sent for reprocessing.
The corpus must reflect real channels, headsets, regions, noise, duration, and call types. A clean promotional recording says little about performance on 8 kHz telephone audio.
A 50–100 call pilot
Choose one process with a clear outcome, such as inbound sales or order confirmation. Collect 50–100 calls that are lawfully available for testing and manually label the critical fields. Split the set into tuning and final evaluation. Do not select thresholds on the same calls used to report quality.
The first release should create a draft and never change the CRM automatically. Review errors weekly by stage: source audio, VAD, ASR, diarization, glossary, LLM, or business rule. This reveals the correct fix. A larger LLM cannot recover a surname that disappeared during speech recognition.
What leaders should take away
Local call transcription is not one model. It is a governed pipeline with evidence and an accountable person at the end. The best entry point is completed calls, batch processing, and a timestamped CRM draft.
The practical next step is to measure daily audio volume, select 50–100 representative calls, define five critical fields, and calculate the cost of one employee-accepted record. If the pilot cannot show the recording segment behind a conclusion, it is too early to enable automatic CRM writes. Vnutrik may listen quickly, but people still own the right to make promises on behalf of the company.