Why good test images do not prove reliable inspection
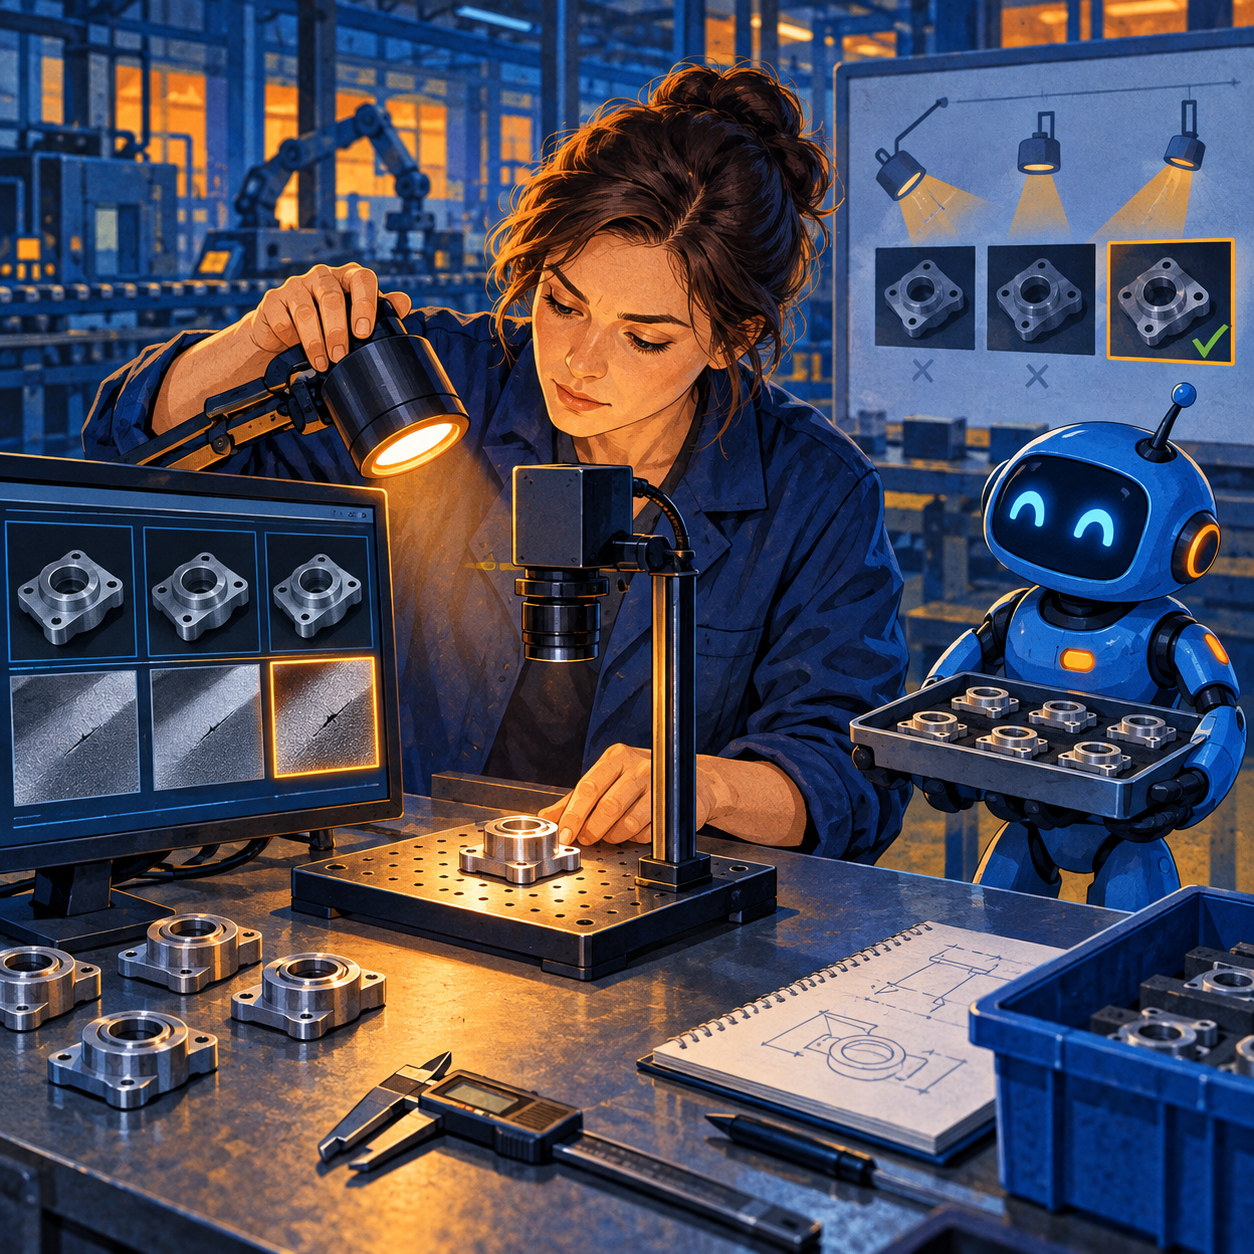
A visual-inspection system may confidently find scratches in a demo dataset and then start rejecting good parts after a lamp is replaced, a new metal batch arrives, or the camera shifts slightly. For a small manufacturer, this is not an academic detail: every false rejection needs another inspection, while a missed defect can lead to rework or a return. A pilot therefore needs to test not just an average accuracy number but robustness to a predefined list of changing conditions.
The MVTec AD 2 research dataset was designed for difficult industrial anomaly-detection scenarios: eight tasks and more than 8,000 high-resolution images. Its normal and defective test images include lighting conditions that need not be present in training. The authors of a separate study, AeBAD, showed how changes in viewpoint and lighting can raise anomaly scores for normal parts and increase false alarms. Neither work guarantees performance in a particular Russian factory; together they identify a risk that belongs in a local pilot.
Separate three questions
First, is the defect visible in the image? An algorithm cannot reliably recover a feature lost to glare, shadow, insufficient resolution or the wrong angle. Before selecting a neural network, fix the positions of the product, camera and light, test several real samples, and record acceptable variation. Include clearly good parts with challenging textures: these are often the expensive false alarms.
Second, can the chosen method distinguish defects from normality? If defects are rare or their types change often, test anomaly detection trained on normal samples. If defect classes are stable and trustworthy labels exist, compare classification or segmentation. For a simple geometric deviation, start with image-processing rules. These are architectural alternatives to compare, not a claim that one particular model will win on your products.
Third, will the solution withstand real changes? Hold out production batches and shifts that were not used to tune the threshold. Test lighting changes, different material suppliers, part position, dirty optics and maintenance events separately. Do not scatter near-identical neighbouring frames of the same part across training and test sets: that makes validation much easier than future operation on a line.
What to measure instead of one percentage
Build a small scenario table. For each scenario, record the number of good and defective parts, missed consequential defects, false rejection of good parts, the proportion of frames sent to a person, and response time. Choose a threshold using the business cost of each error, not the most flattering point on an overall chart. If missing a defect is costly, the system should initially assist the operator rather than issue an autonomous pass/fail verdict.
A shadow run is useful: the algorithm makes a prediction, but existing inspection continues to make the real decision. Match the two logs by part and batch identifier. Check not only correct classifications but also frames that cannot be inspected at all: overexposure, dirt, a missing part or a camera outage. Such cases need an explicit “not inspected” state, not a silent pass. A threshold and model version must be tied to a specific camera and lighting configuration.
A small business need not immediately buy a computing cluster. A camera and local computer can sit near the line, raw images and labels can be kept on a protected server, and results can flow into the quality log. CPU or GPU requirements should follow measurements of image size, line rate and acceptable latency. Start MES or ERP integration with a part identifier, model score and human-confirmed outcome. Automatic line stops are a separate project requiring stricter validation and clear responsibility.
Pilot economics and data licensing
A model calculation for one shift is: false-alarm cost = number of good parts × false-rejection rate × reinspection time × labour cost per minute. Add missed defects, downtime, image storage, labelling of new batches and optical maintenance. This is a formula for your own inputs, not a published MVTec result. Even a small rise in false rejection can erase the benefit of reducing primary manual checks when production volume is high.
The public MVTec AD 2 dataset is useful for studying methods and demonstrating what happens under different lighting. However, it is licensed CC BY-NC-SA 4.0, and its publisher explicitly prohibits commercial use of the data without separate permission. Do not load its images into a commercial product or treat a benchmark score as validation of your own production process. For a real deployment, collect images of your own products on a lawful basis, establish the rights to use them, and restrict access where the pictures reveal product designs or processes.
The realistic next step is a test plan for one inspection operation. Select a product and the costs of both error types, photograph several batches under varying conditions, agree on expert labels and define pilot stop thresholds in advance. Check simple image processing and raw image quality before training a complex model. The pilot should answer two questions: which imaging setup is stable, and what error rates remain on new batches? If robustness is lacking, invest first in light, camera mounting and inspection procedures, not the promise of another “universal” neural network.