The problem: reproducible quality assessment
Big Saint Food is a Spanish microbusiness with 1–9 employees, working with Iberian pork products and services for the agri-food sector. Specialists traditionally assessed the quality of loins and shoulders. Such inspection depends on individual experience, making consistent decisions across shifts, sites, and batches difficult. The company wanted to test whether visual characteristics could support a more systematic classification process.
The European Digital Innovation Hubs Network published the case on 13 July 2026. It does not announce a new model or prove complete automation; it describes a tested prototype for a specific workflow. The lesson is relevant to producers and distributors when grading affects prices, routing, and customer complaints.
Why the team did not buy a 3D scanner
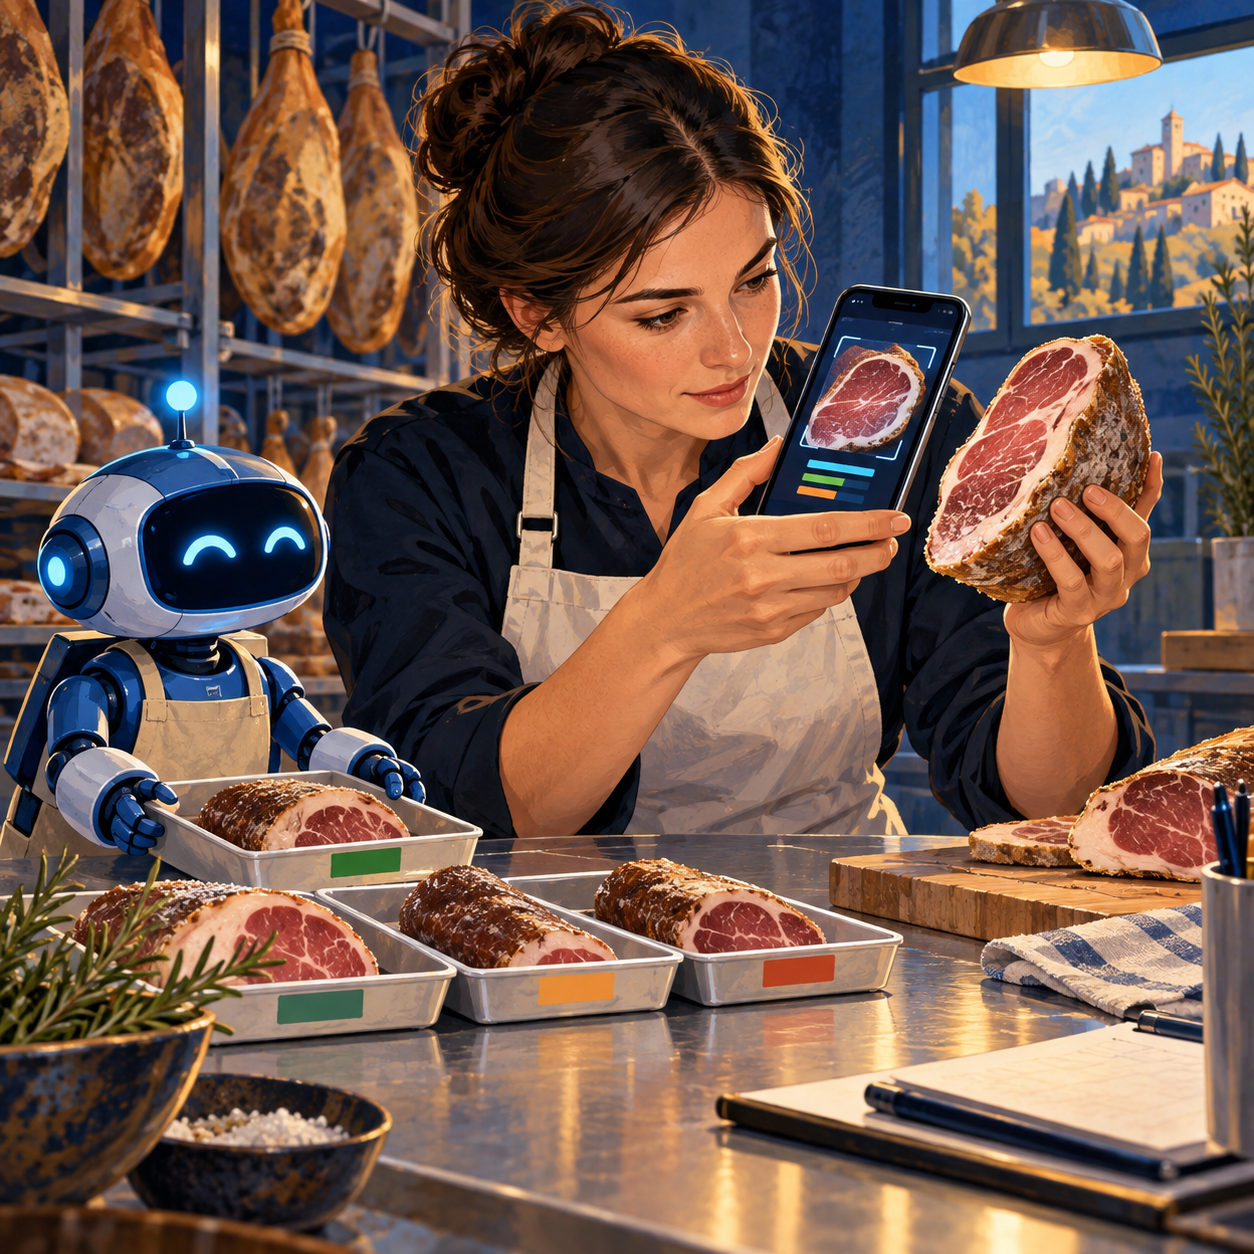
Project partners AIR Institute and DIGIS3 first assessed the production site. They captured initial photographs there to calibrate camera position, tripod use, and a uniform background. The pilot selected 2D images from a standard smartphone instead of 3D scanning. According to the case, this was sufficient to collect the required data for the test and let ordinary operators contribute images without specialised equipment.
Next, machine-learning models were trained and validated to classify product quality from image-derived variables. The evaluation used macro F1, which averages performance across classes rather than allowing a dominant class to hide poor results for a rare one. However, the public case does not disclose the numeric F1 score, dataset size, or confusion matrix. “A smartphone is enough” therefore cannot be generalised to another product without a local test. Our little robot intern has already drawn up a scanner shopping list; it can wait.
The operational platform used a FastAPI back end, Docker containers, and AWS EC2. The source says the company can use it directly. This establishes an accessible prototype, not that every item is graded without human supervision or that an independent certification has been completed.
What was actually measured
Big Saint Food's overall digital-maturity score increased from 33% to 40%, while its automation and AI score rose from 36% to 52%. These are digital-maturity assessment figures, not model accuracy. The case also reports a more systematic quality-assessment process and a proprietary technological asset.
Potential reductions in inspection time, grading errors, and waste have not yet been quantified over a sufficient operating period. The actual cost per graded item is also unpublished. Separately, the company secured €30,000 of funding with support in preparing an application; that funding must not be presented as a return generated by the model.
One caution is especially useful: the data-governance score fell from 52% to 39% in the follow-up assessment. The public account does not explain why. For a pilot producing product photographs and grade decisions, it is a reason to review image storage, labelling versions, staff permissions, and change logs rather than celebrating only the new recognition button.
A short pilot for another business
Start with the decision the system should support: assign a grade, route an item to further inspection, or record a deviation. A quality expert must define classes and borderline examples in writing. If two experienced inspectors disagree, a model will not remove that ambiguity without agreed rules.
- Photograph items from different batches and across acceptable sizes, colours, and surface states. Fix distance, lighting, and background.
- Store each image with a batch identifier, date, and expert decision. A model score is hard to audit without a link to the item and outcome.
- Split data by batch or date, not by randomly distributing near-identical frames of the same item between training and test sets.
- Review macro F1 and errors for every class, but also price the actual business mistakes: an item wrongly downgraded or sold at too high a grade.
- Run a shadow period: the model proposes a grade and the specialist decides. Log disagreements and time spent on reinspection.
A standard camera is not an argument against industrial optics forever. Higher line speed, hygiene requirements, tiny visible features, or different lighting may change the equipment choice. Conversely, if phone images are stable and useful, buying a 3D rig before the evidence is in only adds risk.
Architecture and data for a Russian SME
A minimal flow is: guided capture → image-quality check → storage of image and metadata → classifier → human decision for low confidence and disputed classes → entry in the business system. Integration with ERP or a quality system matters more than an attractive standalone dashboard: grades must reach batch records and documents without retyping.
Big Saint Food ran computation on AWS. A Russian company need not copy that platform. If production images cannot leave the site or predictable latency is required, the server and model can run on premises. That is an engineering option, not the architecture reported in the Spanish case. Either way, define backups, access rights, image retention, and a rollback route if a model update degrades grading.
Economics and a stop criterion
Compare the full cost per expert-accepted decision: capture, labelling, development, cloud server or local PC, integration, support, and human reviews. Value is created only when labour or losses from incorrect grading fall while false alerts remain tolerable. A maturity score or a grant does not establish payback.
The next step is to select one product category, define grades and error costs, collect photographs at the real workplace, and run a shadow evaluation on new batches. Then decide whether to scale, improve capture, or retain expert inspection. The robot intern can arrange the sample trays; a person should still sign off the grade.
Primary source: European Digital Innovation Hubs Network, Big Saint Food case study. Macro F1 is cross-checked with the scikit-learn documentation. On-premises deployment and pilot design are editorial recommendations, not claims made by the company.